Setup
Analyze time-series fluorescence data from PURE (Protein synthesis Using Recombinant Elements) experiments.
Setup
!pip install nucleus-cdk==0.5.0rc2 | tail -n2Requirement already satisfied: asttokens in /opt/homebrew/anaconda3/lib/python3.12/site-packages (from stack-data->ipython>=6.1.0->ipywidgets==8.*->jupyter-bokeh<5.0.0,>=4.0.5->nucleus-cdk==0.5.0rc2) (2.0.5)
Requirement already satisfied: pure-eval in /opt/homebrew/anaconda3/lib/python3.12/site-packages (from stack-data->ipython>=6.1.0->ipywidgets==8.*->jupyter-bokeh<5.0.0,>=4.0.5->nucleus-cdk==0.5.0rc2) (0.2.2)
%load_ext autoreload
%autoreload 2

import pandas as pd
import seaborn as sns
import matplotlib.pyplot as plt

# Import the cdk platereader module
from cdk.analysis.cytosol import platereader as pr

# Set up plotting
pr.plot_setup()
Load Data
# Specify file paths
data_file = "20260120-cytation3-pure-timecourse-gfp-OnePotPURE-Opt-biotek-cdk.txt"
platemap_file = "20260120-OnePotPURE-Opt1-Platemap.csv"

# Load data
data, platemap = pr.load_platereader_data(
    data_file=data_file,
    platemap_file=platemap_file,
    platereader="biotek-cdk"  # Options: "cytation", "envision", "biotek-cdk"
)

# Checkout first few rows
data.head()Plot Raw Curves
g = pr.plot_curves(data=data)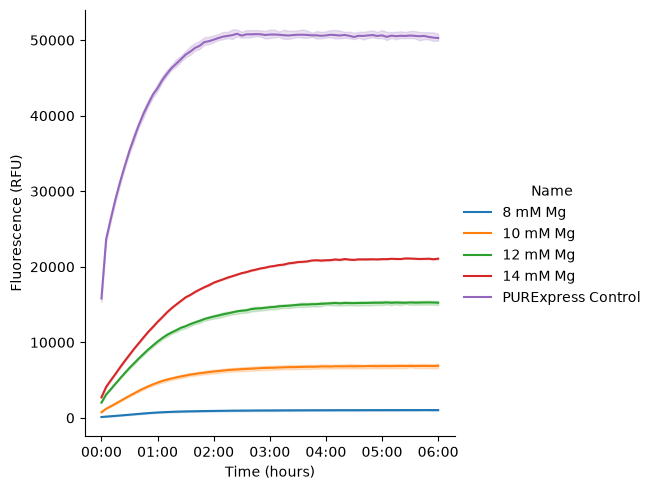
Normalize Data
# No HPTS/fluorescein normalization control present in this platemap's Name column - skipping normalize_data_to_controls, using raw (unnormalized) dataNow replot your curves to see them normalized
g = pr.plot_curves(data=data)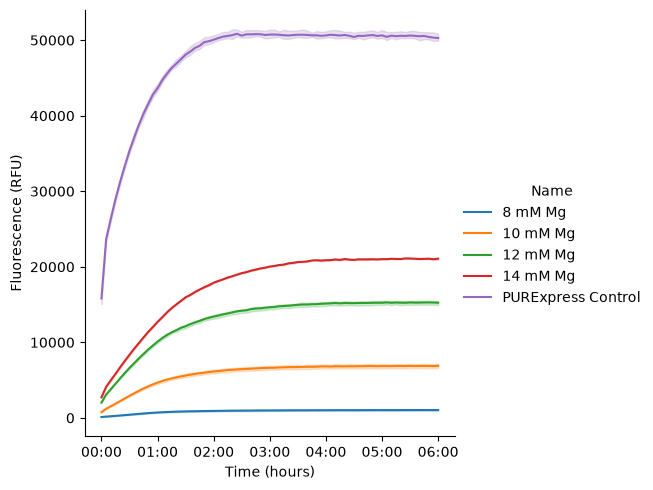
Kinetic Analysis
Metrics extracted:
Vmax (
Velocity Max): Maximum rate of fluorescence increase (slope at inflection point)Lag time: Time to reach the exponential phase
Steady-state: Final fluorescence level and time to reach 95% of asymptote
Drift: Rate of signal decay or increase after steady-state
R²: Goodness of fit
# Perform kinetic analysis using sigmoid_drift model
kinetics = pr.kinetic_analysis(
    data=data,
    group_by=['Name'],  # Group by experimental condition
)

kinetics.head()
PROVIDING AVERAGED KINETICS
Visualize Fits on Individual Wells
# Plot kinetic fits
g = pr.plot_kinetics(data, kinetics=kinetics, group_by=["Name"])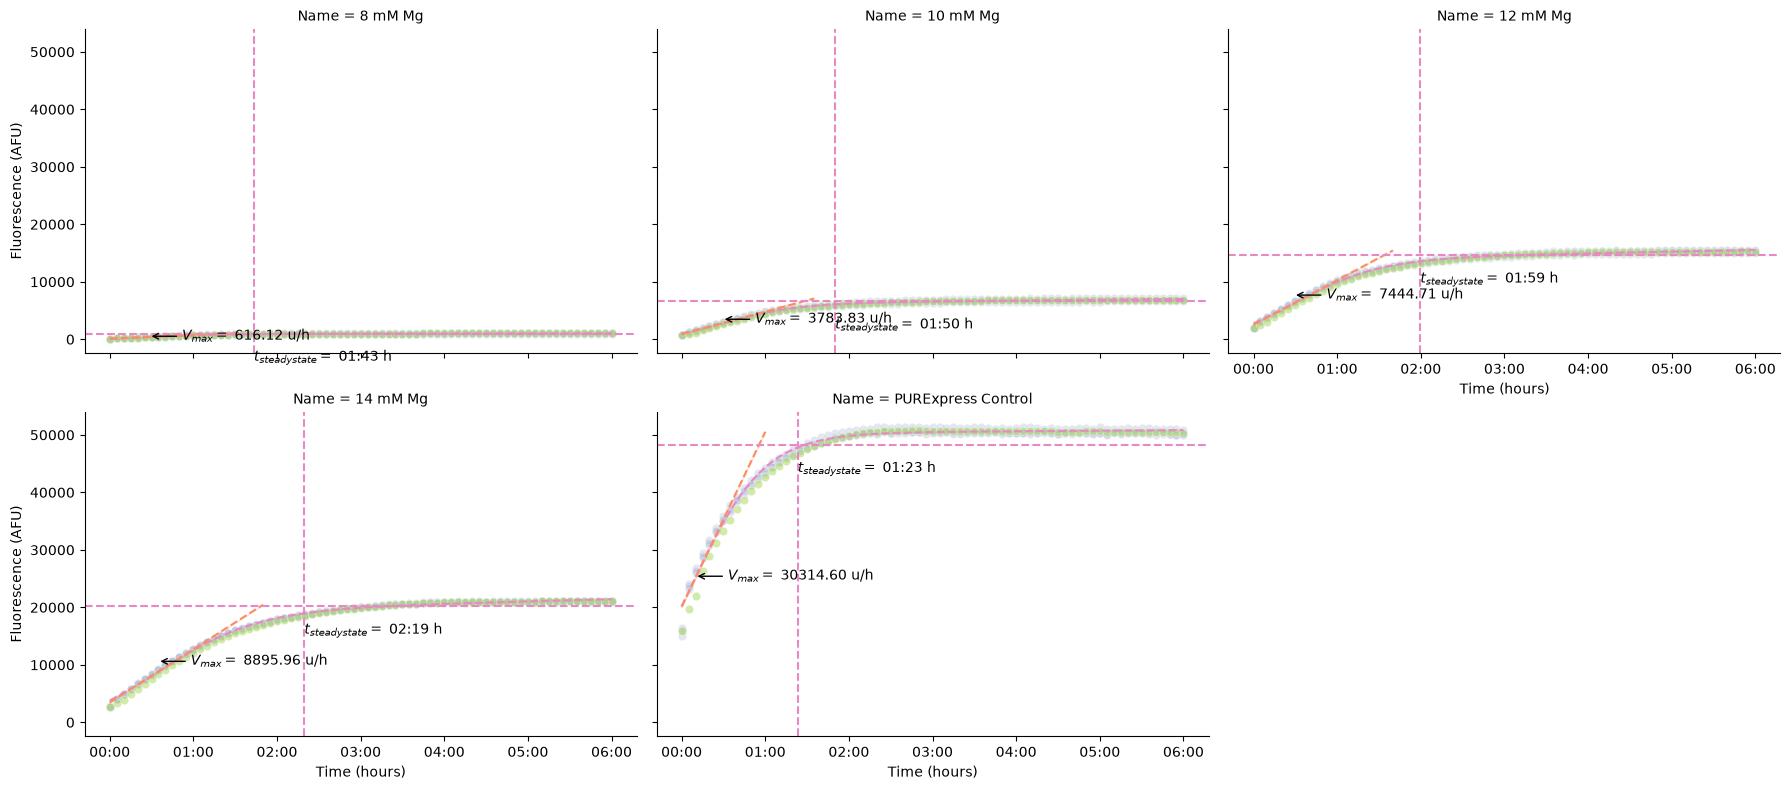
Summary Plots
summary_plot = pr.plot_summary(data)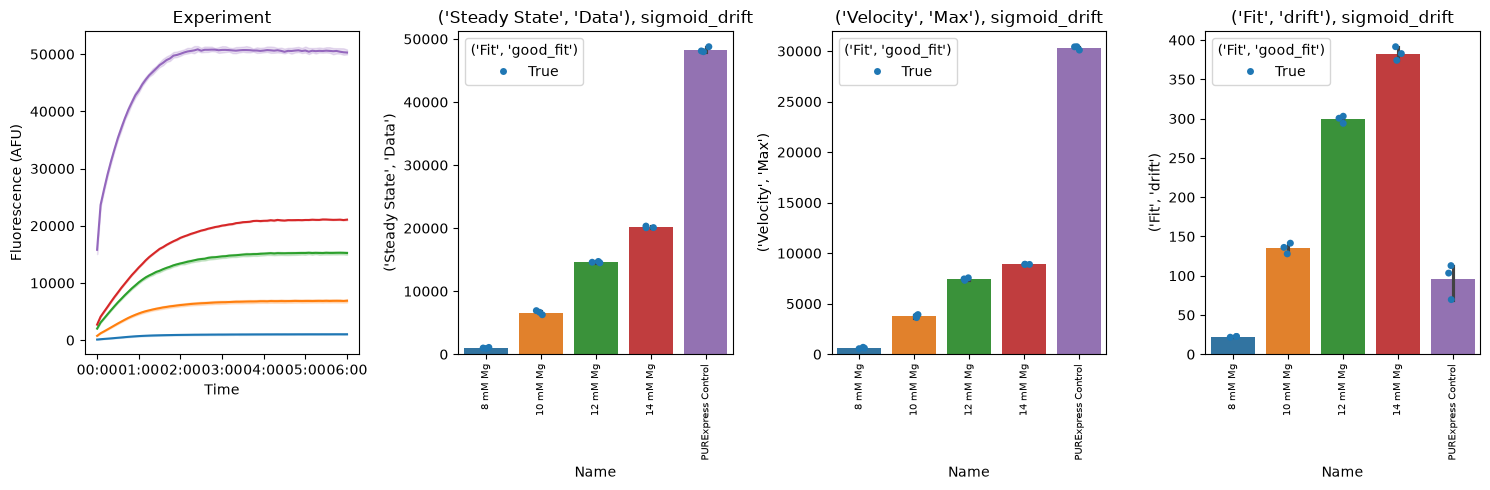
Key Metrics Explained
1. Steady-State Level (Steady State, Data)
The final fluorescence value reached by the reaction
Represents the total amount of protein produced
Higher values indicate greater expression yield
2. Maximum Velocity (Velocity, Max)
The steepest slope of the fluorescence curve (at the inflection point)
Units: RFU per second
Reflects the peak rate of protein synthesis
Sensitive to enzyme activity, substrate availability, and reaction conditions
3. Lag Time (Lag, Time)
Time before exponential fluorescence increase begins
May reflect time for ribosome assembly or initial translation steps
Shorter lag times suggest faster reaction initiation
4. Drift (Fit, drift)
Rate of fluorescence change after reaching steady-state
Positive drift: continued synthesis or aggregation
Negative drift: photobleaching, protein degradation, or quenching
Units: RFU per second
5. R² Value (Fit, R^2)
Goodness of fit (0 to 1, higher is better)
R² > 0.98 indicates excellent fit
Poor fits may indicate noisy data, overflow errors, or non-sigmoid kinetics
Tips and Troubleshooting
Overflow errors: Wells with
OVRFLWorNaNvalues are automatically excluded from fittingPoor fits (low R²): Inspect raw curves for anomalies (bubbles, evaporation, pipetting errors)
Drift: Sometimes seen in kinetics curves; use
sigmoid_driftmodelMultiple replicates: Always include technical replicates and report error bars
Comparing conditions: Normalize or blank data consistently across all samples
Next Steps
Export kinetics results:
pr.export_kinetics(kinetics, 'results.csv')Statistical analysis: Use
scipy.statsorstatsmodelsfor ANOVA/t-testsParameter optimization: Vary Mg²⁺, K⁺, or other conditions to maximize Vmax or steady-state
Mechanistic modeling: Fit ODE models to extract biological rate constants