DNA Titration, Spent EsaR
Analyze time-series data from platereader experiments.
DNA Titration, Spent EsaR
try:
    import cdk
    print("CDK already installed, skipping installation and restart.")
except ImportError:
    !pip install nucleus-cdk -q > /dev/null 2>&1
    print("\nInstallation complete. Restarting runtime to refresh dependencies...")
    import os
    os._exit(0)
CDK already installed, skipping installation and restart.
import pandas as pd
pd.set_option('display.max_columns', None)
import seaborn as sns
import matplotlib.pyplot as plt

# Import the cdk platereader module
from cdk.instruments import platereader as pr

from cdk import logging
log = logging.setup_logging(logging.ERROR)
Load Data
%%writefile drive_utils.py
import os
import re

import gdown


def get_drive_file_id(url):
    """Extract the file ID from a Google Drive share URL."""
    match = re.search(r'/d/([a-zA-Z0-9_-]+)', url)
    if match:
        return match.group(1)
    return None


def download_from_drive(files_info, destination_dir):
    """
    Download files from Google Drive.

    Args:
        files_info (list): List of dicts with 'url' and 'filename'.
        destination_dir (str): Local path to save files.
    Returns:
        dict: Mapping of filenames to local paths.
    """
    os.makedirs(destination_dir, exist_ok=True)

    paths = {}
    for item in files_info:
        url = item['url']
        filename = item['filename']
        dest = os.path.join(destination_dir, filename)
        file_id = get_drive_file_id(url)

        if file_id:
            gdown.download(id=file_id, output=dest, quiet=True)
        else:
            gdown.download(url, output=dest, quiet=True)

        paths[filename] = dest
    return paths
Overwriting drive_utils.py
# Set use_drive = True to download data_file and platemap_file from Google Drive instead of
# using local files. Each Drive file must have its permissions set to "Anyone with a link" can "view".
use_drive = True

if use_drive:
    from drive_utils import download_from_drive

    files_to_download = [
        {
            "url": "https://drive.google.com/file/d/1oB_drvnZlumdGA3YeNzLriyyOfpD0Tf2/view?usp=share_link",  # Replace with your data file link.
            "filename": "raw_data.txt",
        },
        {
            "url": "https://drive.google.com/file/d/14mr1h7jZeJneQKCLnzcGVZnuyMuyPIkv/view?usp=share_link",  # Replace with your platemap file link.
            "filename": "platemap.csv",
        },
    ]
    downloaded_paths = download_from_drive(files_to_download, destination_dir="data")
    data_file = downloaded_paths["raw_data.txt"]
    platemap_file = downloaded_paths["platemap.csv"]
else:
    data_file = "sample-data/20251111-122213-cytation5-pure-timecourse-gfp-MFG-98-tRNA-QC.txt"
    platemap_file = "sample-data/platemap.csv"

print(f"Data file: {data_file}\nPlatemap file: {platemap_file}")
Data file: data/raw_data.txt
Platemap file: data/platemap.csv
# Load data
result = pr.load_platereader_data(
    data_file=data_file,
    platemap_file=platemap_file,
    platereader="biotek" # options: "biotek"
)
The output is a list of PlateReaderResult objects; if you did more than one read on the plate reader, the results will be in separate objects.
print(result)PlateReaderResult with the following 3 blocks:
0: (2117, 40) kinetic read with reads: GFP-G50:485/20,528/20 (Fluorescence) (Plate 'Plate 1')
1: (2117, 40) kinetic read with reads: GFP-G35:485/20,528/20 (Fluorescence) (Plate 'Plate 1')
2: (348, 38) endpoint read with reads: Max V [GFP-G50:485/20,528/20] (Fluorescence), R-Squared [GFP-G50:485/20,528/20] (Fluorescence), t at Max V [GFP-G50:485/20,528/20] (Fluorescence), Lagtime [GFP-G50:485/20,528/20] (Fluorescence), Max V [GFP-G35:485/20,528/20] (Fluorescence), R-Squared [GFP-G35:485/20,528/20] (Fluorescence), t at Max V [GFP-G35:485/20,528/20] (Fluorescence), Lagtime [GFP-G35:485/20,528/20] (Fluorescence), Count (None), Mean (None), Std Dev (None), CV (%) (None) (Plate 'Plate 1')
Here there were two reads with different gains but the same excitation/emission spectrum, on one plate. If we want just the GFP-Gext read, this corresponds to block index 1, so we can extract that block by indexing:
desired_index = 1
data = result[desired_index]
You can see the underlying data with data.view() (which returns a Pandas DataFrame):
data.view().head()data.plot(style='Type')<seaborn.axisgrid.FacetGrid at 0x796d7c816cf0>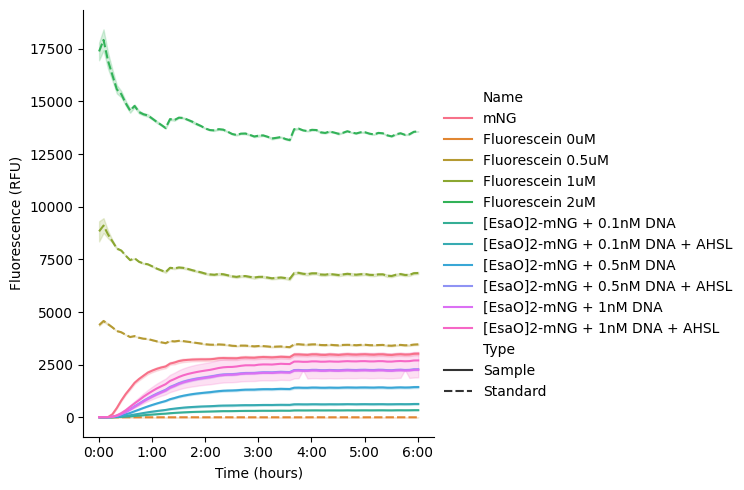
Plot Raw Curves
data_EsaO2_01 = data.select(name=["[EsaO]2-mNG + 0.1nM DNA", "[EsaO]2-mNG + 0.1nM DNA + AHSL"])
data_EsaO2_05 = data.select(name=["[EsaO]2-mNG + 0.5nM DNA", "[EsaO]2-mNG + 0.5nM DNA + AHSL"])
data_EsaO2_1 = data.select(name=["[EsaO]2-mNG + 1nM DNA", "[EsaO]2-mNG + 1nM DNA + AHSL"])

df_1 = data_EsaO2_01.data
df_2 = data_EsaO2_05.data
df_3 = data_EsaO2_1.data


# convert timedelta -> float hours
for df in (df_1, df_2, df_3):
    df['Time_hrs'] = df['Time'].dt.total_seconds() / 3600

fig, (ax1, ax2, ax3) = plt.subplots(1, 3, figsize=(13,8), sharey=True)
fig.suptitle('~ 576 nM EsaR / 5 µM AHSL', x=0.55)

sns.lineplot(data=df_1, x='Time_hrs', y='Data', hue='Name', ax=ax1)
sns.lineplot(data=df_2, x='Time_hrs', y='Data', hue='Name', ax=ax2)
sns.lineplot(data=df_3, x='Time_hrs', y='Data', hue='Name', ax=ax3, units='Well', estimator=None)

ax1.set(title='0.1 nM', ylabel='', xlabel='')
ax2.set(title='0.5 nM', ylabel='', xlabel='')
ax3.set(title='1 nM', ylabel='', xlabel='')

fig.supxlabel('Time (hrs)', x=0.55)
fig.supylabel('Fluorescence units')

for ax in (ax1, ax2, ax3):
    ax.legend(frameon=False)

ax1.legend(loc='upper center', bbox_to_anchor=(0.64, 0.1), frameon=False)
ax2.legend(loc='upper center', bbox_to_anchor=(0.64, 0.1), frameon=False)


sns.despine(fig)
fig.tight_layout()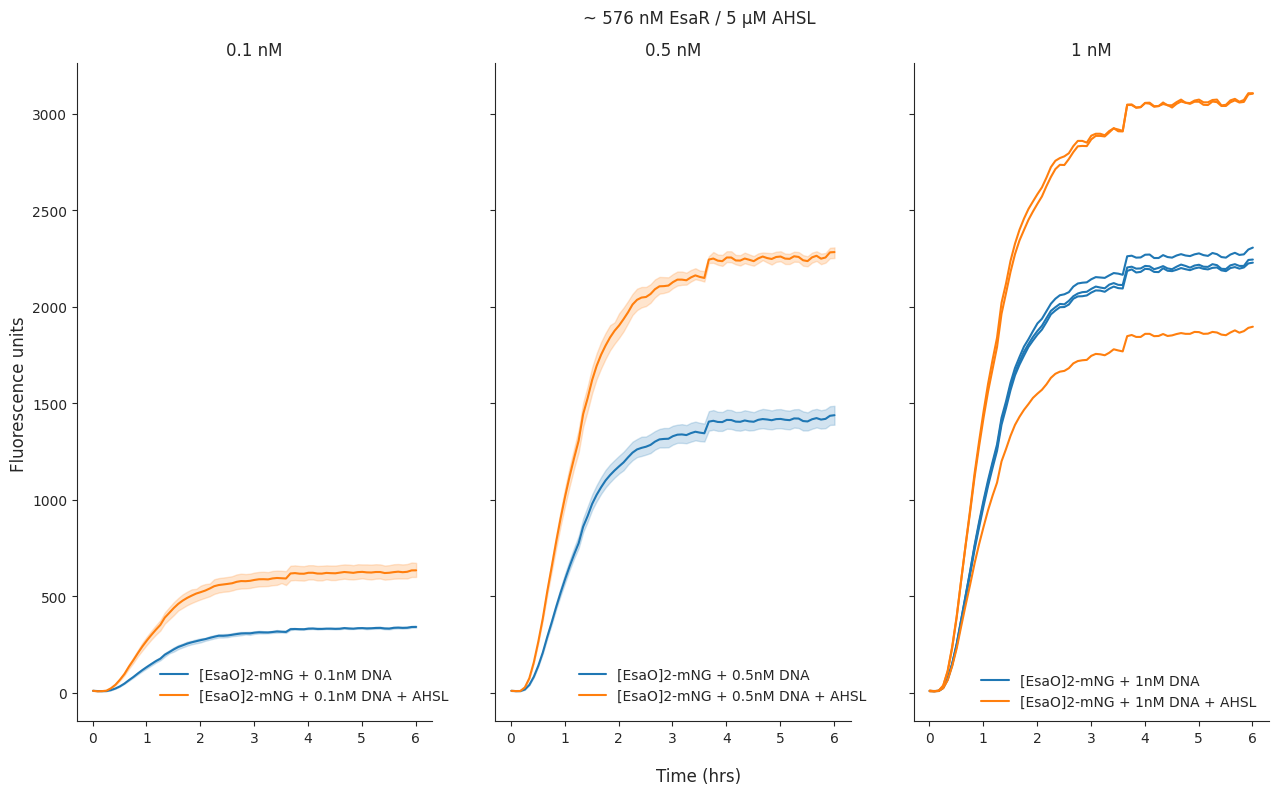
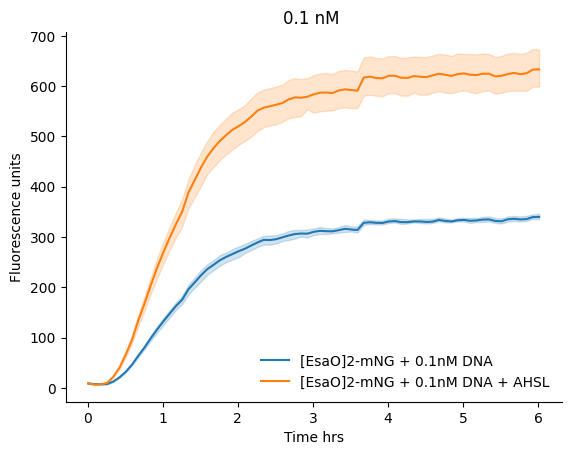
sns.lineplot(data=df_1, x='Time_hrs', y='Data', hue='Name')

plt.title("0.1 nM ")
plt.xlabel("Time hrs")
plt.ylabel("Fluorescence units")
plt.legend(frameon=False)
sns.despine()
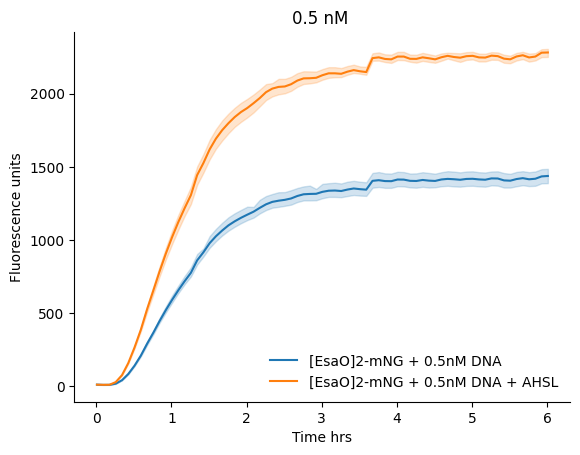
sns.lineplot(data=df_2, x='Time_hrs', y='Data', hue='Name')

plt.title("0.5 nM ")
plt.xlabel("Time hrs")
plt.ylabel("Fluorescence units")
plt.legend(frameon=False)
sns.despine()
sns.lineplot(data=df_3, x='Time_hrs', y='Data', hue='Name', units="Well", estimator = None)

plt.title("1 nM ")
plt.xlabel("Time hrs")
plt.ylabel("Fluorescence units")
plt.legend(frameon=False)
sns.despine()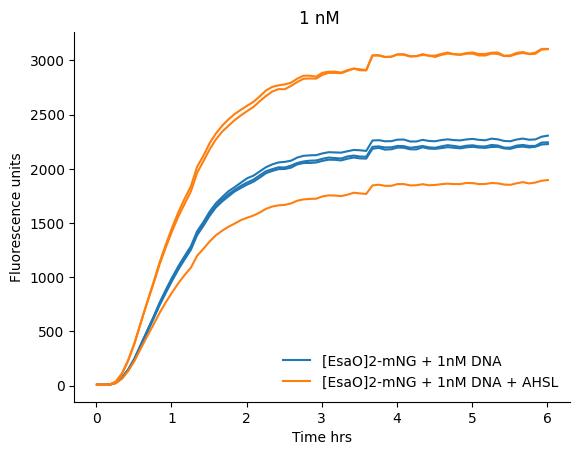
def steady_state_fold_change(df, base_name, ahsl_name, n_last=10):
    tail = df.groupby('Name').apply(lambda g: g.nlargest(n_last, 'Time_hrs')['Data'].mean())
    return tail[ahsl_name] / tail[base_name]

fc_01 = steady_state_fold_change(df_1, "[EsaO]2-mNG + 0.1nM DNA", "[EsaO]2-mNG + 0.1nM DNA + AHSL")
fc_05 = steady_state_fold_change(df_2, "[EsaO]2-mNG + 0.5nM DNA", "[EsaO]2-mNG + 0.5nM DNA + AHSL")
fc_1  = steady_state_fold_change(df_3, "[EsaO]2-mNG + 1nM DNA",   "[EsaO]2-mNG + 1nM DNA + AHSL")

# --- tidy into one summary table ---
fold_summary = pd.DataFrame({
    'DNA_conc_nM': [0.1, 0.5, 1],
    'Fold_change': [fc_01, fc_05, fc_1]
})
print(fold_summary)
   DNA_conc_nM  Fold_change
0          0.1     1.871863
1          0.5     1.589792
2          1.0     1.162061
/tmp/ipykernel_1683/2813574122.py:2: DeprecationWarning: DataFrameGroupBy.apply operated on the grouping columns. This behavior is deprecated, and in a future version of pandas the grouping columns will be excluded from the operation. Either pass `include_groups=False` to exclude the groupings or explicitly select the grouping columns after groupby to silence this warning.
  tail = df.groupby('Name').apply(lambda g: g.nlargest(n_last, 'Time_hrs')['Data'].mean())
fig, ax = plt.subplots(figsize=(6,5))

sns.barplot(data=fold_summary, x='DNA_conc_nM', y='Fold_change', ax=ax, color='tab:orange')

ax.set(xlabel='DNA concentration (nM)', ylabel='Fold change (+AHSL / −AHSL)')
ax.set_title('Steady-state AHSL fold induction — [EsaO]2')
ax.axhline(1, color='grey', linestyle='--', linewidth=1)

sns.despine(fig)
fig.tight_layout()
plt.show()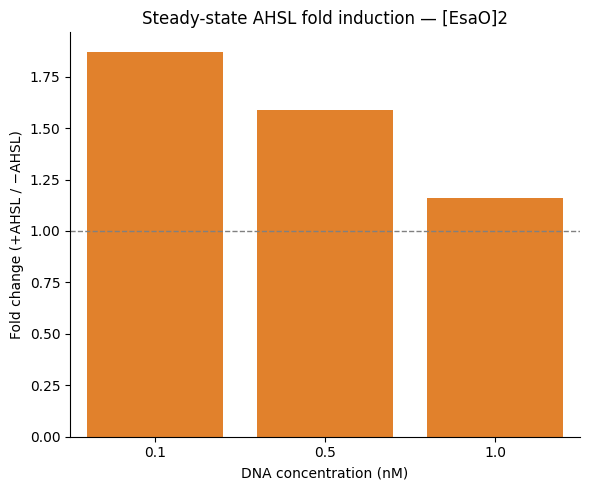
We can see that the standard (here, HPTS) is stable and can be safely used for normalization.
Normalize Data
Now, use data.normalize('<standard name>') to normalize your data. This will calculate the average over a time window at the end of the experiment (by default, 1 hour), then divide all data by the mean of that window-average across all wells with the same Name (defined by your platemap).
# To check the exact name of your standard
platemap = data.platemap
standards = platemap[platemap['Type']=='Standard']
standards['Name'].unique()
array(['Fluorescein 0uM', 'Fluorescein 0.5uM', 'Fluorescein 1uM',
'Fluorescein 2uM'], dtype=object)data = data.normalize('Fluorescein 0.5uM')Now replot your curves to see them normalized:
g = data.plot(style='Type', exclude_types=['Standard'])
# g.savefig('after-normalization.png',dpi=300)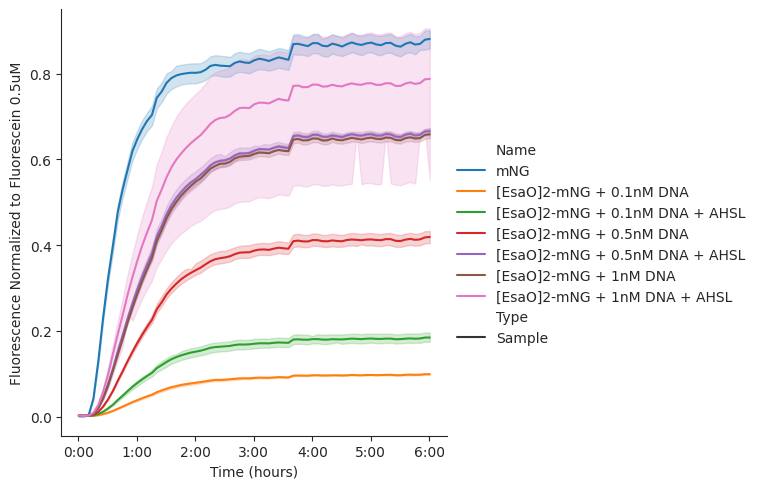
Side-by-Side Comparison with Exported Data
Load and compare your previously exported normalized dataset side-by-side with the current normalized plate reader data.
# Get the normalized view of the current data
df_current_norm = data.normalize('Fluorescein 0.5uM').view().copy()

# Filter out standards to keep only the experimental samples
df_current_samples_only = df_current_norm[df_current_norm['Type'] != 'Standard']

# Export to a CSV file
output_filename = 'normalized_current_run.csv'
df_current_samples_only.to_csv(output_filename, index=False)
print(f"Successfully exported normalized samples to {output_filename}")
Successfully exported normalized samples to normalized_current_run.csv
#!/usr/bin/env python3
"""
Side-by-side plate-reader kinetics with a shared y-axis (seaborn).

Edit the CONFIG block below, then run:
    python plot_panels_seaborn.py
"""
import matplotlib.pyplot as plt
import pandas as pd
import seaborn as sns

# =============================================================================
# CONFIG — edit these
# =============================================================================

# One dict per panel, left -> right.
#   file    : CSV path
#   title   : panel title (mathtext $\mathbf{...}$ makes that part bold)
#   include : substring(s) a sample Name must contain to be plotted (None = all)
#   exclude : substring(s) that drop a sample Name (None = nothing dropped)
#   extra   : exact sample Name(s) to add on top of `include` (e.g. the "mNG" control)
PANELS = [
    dict(file="normalized_current_run.csv",
         title=r"Pre-expressed EsaR $\mathbf{(30\ ^{\circ}C,\ 17\ hours)}$",
         include=["[EsaO]2-mNG"], exclude=None, extra=["mNG"]),
    dict(file="normalized_samples_only.csv",
         title=r"Pre-expressed EsaR $\mathbf{(37^{\circ}C,\ 3\ hours)}$",
         include=["[EsaO]2-mNG"], exclude=None, extra=["mNG"]),
]

Y_LABEL = "Normalized RFU (0.5 µM Fluorescein)"
X_LABEL = "Time (hrs)"

# What to plot on y:
#   "normalized" -> Data_normalized (fluorescein-calibrated; comparable across days)
#   "raw"        -> raw counts (uses Data_raw if present, otherwise Data)
Y_DATA = "normalized"

# Line grouping. Any column of the CSV works, e.g. "Name", "DNA Template (nM)", "AHSL".
HUE = "Name"          # colour
STYLE = None          # line dash (e.g. "AHSL"); None = all solid
PALETTE = "tab10"     # seaborn palette name, or a list of colours
COLOR_OVERRIDES = {"mNG": "black"}   # fix colours for specific hue values

ERRORBAR = "sd"       # "sd", ("ci", 95), "se", or None for no band
SHARE_Y = True
Y_LIM = None          # e.g. (0, 4500); None = auto
X_LIM = None          # e.g. (0, 6)

FIGSIZE = (11, 4.8)
# Legend placement:
#   "shared" -> one legend under the figure (best when there are many lines)
#   "each"   -> a legend inside every panel at LEGEND_LOC (like the reference plot)
LEGEND_MODE = "shared"
LEGEND_LOC = "lower right"   # used when LEGEND_MODE = "each"
LEGEND_NCOL = 3              # used when LEGEND_MODE = "shared"
LEGEND_FONTSIZE = 10

# Fonts — set to match the RFU figure (matplotlib defaults: DejaVu Sans, 10 pt base)
FONT_FAMILY = "DejaVu Sans"
TICK_FONTSIZE = 10
TITLE_FONTSIZE = 12          # panel titles
LABEL_FONTSIZE = 10          # x / y axis labels
OUTFILE = "panels_seaborn.png"
DPI = 200

# =============================================================================


def load_panel(cfg):
    df = pd.read_csv(cfg["file"])

    # Filter sample names
    keep = pd.Series(True, index=df.index)
    if cfg.get("include"):
        keep = df["Name"].apply(lambda n: any(s in n for s in cfg["include"]))
    if cfg.get("exclude"):
        keep &= ~df["Name"].apply(lambda n: any(s in n for s in cfg["exclude"]))
    if cfg.get("extra"):
        keep |= df["Name"].isin(cfg["extra"])
    df = df[keep].copy()

    # y column
    if Y_DATA == "raw":
        df["y"] = df["Data_raw"] if "Data_raw" in df.columns else df["Data"]
    else:
        df["y"] = df["Data_normalized"]

    # Time in hours, aligned across replicate wells (they are read seconds apart)
    df["hours_raw"] = pd.to_timedelta(df["Time"]).dt.total_seconds() / 3600
    df["read_idx"] = df.groupby("Well").cumcount()
    df["hours"] = df.groupby("read_idx")["hours_raw"].transform("mean")

    # Handy grouping column
    df["AHSL"] = df["[AHSL] (uM)"].fillna(0).gt(0).map({True: "+ AHSL", False: "– AHSL"})
    return df


def main():
    sns.set_style("ticks")
    # seaborn's style switches the font list to Arial-first; force the publication font
    plt.rcParams.update({
        "font.family": "sans-serif",
        "font.sans-serif": [FONT_FAMILY],
        "font.size": TICK_FONTSIZE,
        "xtick.labelsize": TICK_FONTSIZE,
        "ytick.labelsize": TICK_FONTSIZE,
        "mathtext.fontset": "dejavusans",
        # nothing bold by default: only the \mathbf{...} part of the panel titles
        "font.weight": "normal",
        "axes.titleweight": "normal",
        "axes.labelweight": "normal",
        "figure.titleweight": "normal",
        "figure.labelweight": "normal",
    })
    data = [load_panel(p) for p in PANELS]

    # Consistent colours across panels: one colour per hue value, shared by all panels
    hue_order = sorted(pd.concat(d[HUE] for d in data).unique(), key=str) if HUE else None
    if HUE:
        others = [h for h in hue_order if h not in COLOR_OVERRIDES]
        colors = dict(zip(others, sns.color_palette(PALETTE, len(others))))
        colors.update({h: c for h, c in COLOR_OVERRIDES.items() if h in hue_order})
    else:
        colors = None

    fig, axes = plt.subplots(1, len(PANELS), figsize=FIGSIZE, sharey=SHARE_Y, squeeze=False)
    axes = axes[0]

    for ax, cfg, df in zip(axes, PANELS, data):
        sns.lineplot(
            data=df, x="hours", y="y",
            hue=HUE, hue_order=[h for h in hue_order if h in set(df[HUE])] if HUE else None,
            palette=colors, style=STYLE,
            errorbar=ERRORBAR, ax=ax,
        )
        ax.set_title(cfg["title"], fontsize=TITLE_FONTSIZE, fontweight="normal")
        ax.set_xlabel("")
        ax.set_ylabel("")
        if X_LIM:
            ax.set_xlim(X_LIM)
        if ax.get_legend():
            if LEGEND_MODE == "each":
                sns.move_legend(ax, LEGEND_LOC, frameon=False, fontsize=LEGEND_FONTSIZE, title=None)
            else:
                ax.get_legend().remove()

    if Y_LIM:
        axes[0].set_ylim(Y_LIM)
    axes[0].set_ylabel(Y_LABEL, fontsize=LABEL_FONTSIZE, fontweight="normal")
    fig.supxlabel(X_LABEL, fontsize=LABEL_FONTSIZE, fontweight="normal")
    sns.despine(fig)

    if LEGEND_MODE == "shared" and (HUE or STYLE):
        # Collect unique entries across all panels
        seen = {}
        for ax in axes:
            for h, l in zip(*ax.get_legend_handles_labels()):
                seen.setdefault(l, h)
        fig.legend(seen.values(), seen.keys(), loc="lower center", ncol=LEGEND_NCOL,
                   frameon=False, fontsize=LEGEND_FONTSIZE, bbox_to_anchor=(0.5, -0.02))
        fig.tight_layout(rect=(0, 0.04 + 0.045 * -(-len(seen) // LEGEND_NCOL), 1, 1))
        fig.supxlabel(X_LABEL, fontsize=LABEL_FONTSIZE, fontweight="normal",
                      y=0.03 + 0.045 * -(-len(seen) // LEGEND_NCOL))
    else:
        fig.tight_layout()
    fig.savefig(OUTFILE, dpi=DPI, bbox_inches="tight")

if __name__ == "__main__":
    main()
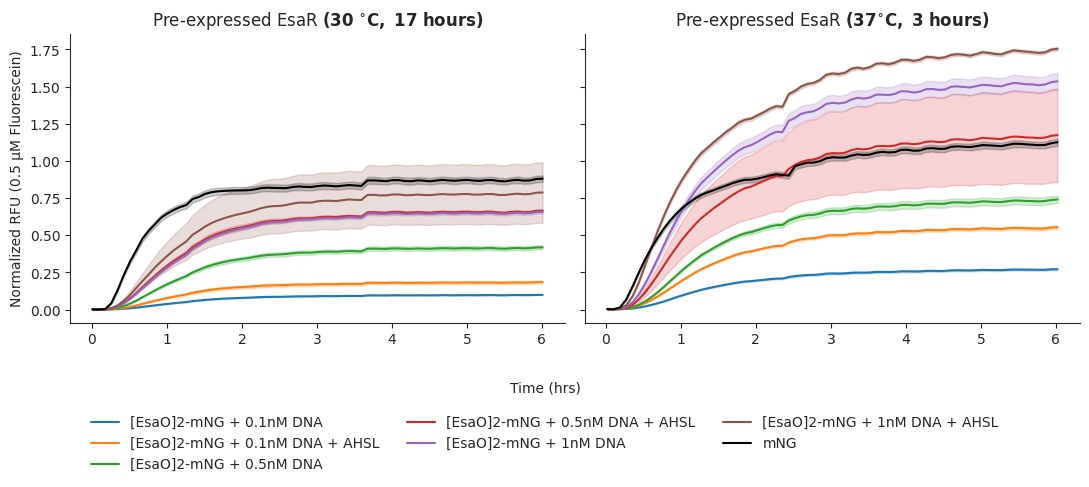
#!/usr/bin/env python3
"""
Side-by-side plate-reader kinetics with a shared y-axis (seaborn).

Edit the CONFIG block below, then run:
    python plot_panels_seaborn.py
"""
import matplotlib.pyplot as plt
import pandas as pd
import seaborn as sns

# =============================================================================
# CONFIG — edit these
# =============================================================================

# One dict per panel, left -> right.
#   file    : CSV path
#   title   : panel title (mathtext $\mathbf{...}$ makes that part bold)
#   include : substring(s) a sample Name must contain to be plotted (None = all)
#   exclude : substring(s) that drop a sample Name (None = nothing dropped)
#   extra   : exact sample Name(s) to add on top of `include` (e.g. the "mNG" control)
PANELS = [
    dict(file="normalized_samples_only.csv",
         title=r"Pre-expressed EsaR $\mathbf{(37^{\circ}C,\ 3\ hours)}$",
         include=["[EsaO]2-mNG + 1nM DNA"], exclude=None, extra=["mNG"]),
    dict(file="normalized_current_run.csv",
         title=r"Pre-expressed EsaR $\mathbf{(30\ ^{\circ}C,\ 17\ hours)}$",
         include=["[EsaO]2-mNG + 1nM DNA"], exclude=None, extra=["mNG"]),
]

Y_LABEL = "Normalized RFU (0.5 µM Fluorescein)"
X_LABEL = "Time (hrs)"

# What to plot on y:
#   "normalized" -> Data_normalized (fluorescein-calibrated; comparable across days)
#   "raw"        -> raw counts (uses Data_raw if present, otherwise Data)
Y_DATA = "normalized"

# Line grouping. Any column of the CSV works, e.g. "Name", "DNA Template (nM)", "AHSL".
HUE = "Name"          # colour
STYLE = None          # line dash (e.g. "AHSL"); None = all solid
PALETTE = "tab10"     # seaborn palette name, or a list of colours
COLOR_OVERRIDES = {"mNG": "black"}   # fix colours for specific hue values

ERRORBAR = "sd"       # "sd", ("ci", 95), "se", or None for no band
SHARE_Y = True
Y_LIM = None          # e.g. (0, 4500); None = auto
X_LIM = None          # e.g. (0, 6)

FIGSIZE = (11, 4.8)
# Legend placement:
#   "shared" -> one legend under the figure (best when there are many lines)
#   "each"   -> a legend inside every panel at LEGEND_LOC (like the reference plot)
LEGEND_MODE = "shared"
LEGEND_LOC = "lower right"   # used when LEGEND_MODE = "each"
LEGEND_NCOL = 3              # used when LEGEND_MODE = "shared"
LEGEND_FONTSIZE = 10

# Fonts — set to match the RFU figure (matplotlib defaults: DejaVu Sans, 10 pt base)
FONT_FAMILY = "DejaVu Sans"
TICK_FONTSIZE = 10
TITLE_FONTSIZE = 12          # panel titles
LABEL_FONTSIZE = 10          # x / y axis labels
OUTFILE = "panels_seaborn.png"
DPI = 200

# =============================================================================


def load_panel(cfg):
    df = pd.read_csv(cfg["file"])

    # Filter sample names
    keep = pd.Series(True, index=df.index)
    if cfg.get("include"):
        keep = df["Name"].apply(lambda n: any(s in n for s in cfg["include"]))
    if cfg.get("exclude"):
        keep &= ~df["Name"].apply(lambda n: any(s in n for s in cfg["exclude"]))
    if cfg.get("extra"):
        keep |= df["Name"].isin(cfg["extra"])
    df = df[keep].copy()

    # y column
    if Y_DATA == "raw":
        df["y"] = df["Data_raw"] if "Data_raw" in df.columns else df["Data"]
    else:
        df["y"] = df["Data_normalized"]

    # Time in hours, aligned across replicate wells (they are read seconds apart)
    df["hours_raw"] = pd.to_timedelta(df["Time"]).dt.total_seconds() / 3600
    df["read_idx"] = df.groupby("Well").cumcount()
    df["hours"] = df.groupby("read_idx")["hours_raw"].transform("mean")

    # Handy grouping column
    df["AHSL"] = df["[AHSL] (uM)"].fillna(0).gt(0).map({True: "+ AHSL", False: "– AHSL"})
    return df


def main():
    sns.set_style("ticks")
    # seaborn's style switches the font list to Arial-first; force the publication font
    plt.rcParams.update({
        "font.family": "sans-serif",
        "font.sans-serif": [FONT_FAMILY],
        "font.size": TICK_FONTSIZE,
        "xtick.labelsize": TICK_FONTSIZE,
        "ytick.labelsize": TICK_FONTSIZE,
        "mathtext.fontset": "dejavusans",
        # nothing bold by default: only the \mathbf{...} part of the panel titles
        "font.weight": "normal",
        "axes.titleweight": "normal",
        "axes.labelweight": "normal",
        "figure.titleweight": "normal",
        "figure.labelweight": "normal",
    })
    data = [load_panel(p) for p in PANELS]

    # Consistent colours across panels: one colour per hue value, shared by all panels
    hue_order = sorted(pd.concat(d[HUE] for d in data).unique(), key=str) if HUE else None
    if HUE:
        others = [h for h in hue_order if h not in COLOR_OVERRIDES]
        colors = dict(zip(others, sns.color_palette(PALETTE, len(others))))
        colors.update({h: c for h, c in COLOR_OVERRIDES.items() if h in hue_order})
    else:
        colors = None

    fig, axes = plt.subplots(1, len(PANELS), figsize=FIGSIZE, sharey=SHARE_Y, squeeze=False)
    axes = axes[0]

    for ax, cfg, df in zip(axes, PANELS, data):
        sns.lineplot(
            data=df, x="hours", y="y",
            hue=HUE, hue_order=[h for h in hue_order if h in set(df[HUE])] if HUE else None,
            palette=colors, style=STYLE,
            errorbar=ERRORBAR, ax=ax,
        )
        ax.set_title(cfg["title"], fontsize=TITLE_FONTSIZE, fontweight="normal")
        ax.set_xlabel("")
        ax.set_ylabel("")
        if X_LIM:
            ax.set_xlim(X_LIM)
        if ax.get_legend():
            if LEGEND_MODE == "each":
                sns.move_legend(ax, LEGEND_LOC, frameon=False, fontsize=LEGEND_FONTSIZE, title=None)
            else:
                ax.get_legend().remove()

    if Y_LIM:
        axes[0].set_ylim(Y_LIM)
    axes[0].set_ylabel(Y_LABEL, fontsize=LABEL_FONTSIZE, fontweight="normal")
    fig.supxlabel(X_LABEL, fontsize=LABEL_FONTSIZE, fontweight="normal")
    sns.despine(fig)

    if LEGEND_MODE == "shared" and (HUE or STYLE):
        # Collect unique entries across all panels
        seen = {}
        for ax in axes:
            for h, l in zip(*ax.get_legend_handles_labels()):
                seen.setdefault(l, h)
        fig.legend(seen.values(), seen.keys(), loc="lower center", ncol=LEGEND_NCOL,
                   frameon=False, fontsize=LEGEND_FONTSIZE, bbox_to_anchor=(0.5, -0.02))
        fig.tight_layout(rect=(0, 0.04 + 0.045 * -(-len(seen) // LEGEND_NCOL), 1, 1))
        fig.supxlabel(X_LABEL, fontsize=LABEL_FONTSIZE, fontweight="normal",
                      y=0.03 + 0.045 * -(-len(seen) // LEGEND_NCOL))
    else:
        fig.tight_layout()
    fig.savefig(OUTFILE, dpi=DPI, bbox_inches="tight")

if __name__ == "__main__":
    main()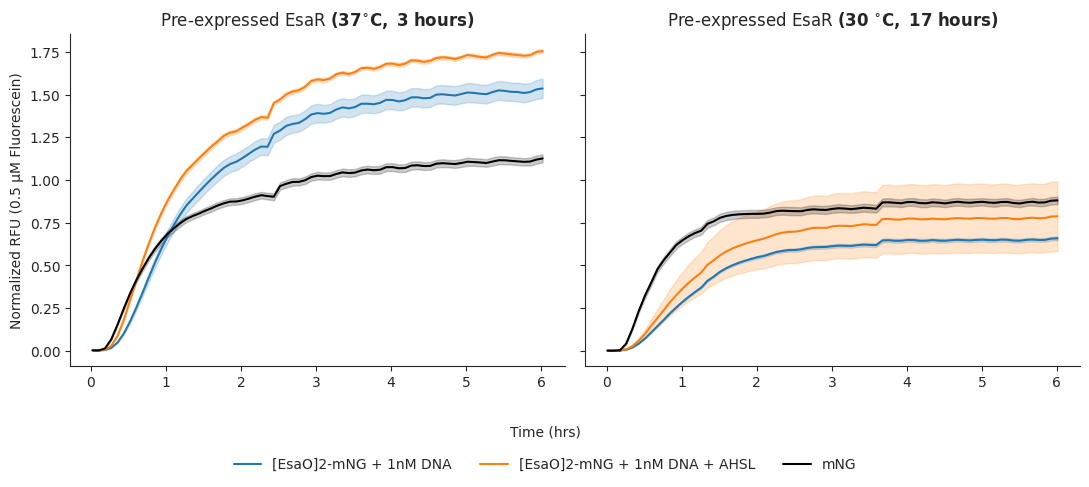
#!/usr/bin/env python3
"""
Side-by-side plate-reader kinetics with a shared y-axis (seaborn).

Edit the CONFIG block below, then run:
    python plot_panels_seaborn.py
"""
import matplotlib.pyplot as plt
import pandas as pd
import seaborn as sns

# =============================================================================
# CONFIG — edit these
# =============================================================================

# One dict per panel, left -> right.
#   file    : CSV path
#   title   : panel title (mathtext $\mathbf{...}$ makes that part bold)
#   include : substring(s) a sample Name must contain to be plotted (None = all)
#   exclude : substring(s) that drop a sample Name (None = nothing dropped)
#   extra   : exact sample Name(s) to add on top of `include` (e.g. the "mNG" control)
PANELS = [
    dict(file="normalized_samples_only.csv",
         title=r"Pre-expressed EsaR $\mathbf{(37^{\circ}C,\ 3\ hours)}$",
         include=["[EsaO]2-mNG + 1nM DNA"], exclude=None, extra=["mNG"]),
    dict(file="normalized_current_run.csv",
         title=r"Pre-expressed EsaR $\mathbf{(30\ ^{\circ}C,\ 17\ hours)}$",
         include=["[EsaO]2-mNG + 1nM DNA"], exclude=None, extra=["mNG"]),
]

Y_LABEL = "Normalized RFU (0.5 µM Fluorescein)"
X_LABEL = "Time (hrs)"

# What to plot on y:
#   "normalized" -> Data_normalized (fluorescein-calibrated; comparable across days)
#   "raw"        -> raw counts (uses Data_raw if present, otherwise Data)
Y_DATA = "normalized"

# Batch correction to the mNG (-EsaR) control. Each file is multiplied by
# (common mNG level / that file's own mNG level), so the y-axis stays in
# normalized fluorescence units but PURE batch-to-batch offsets cancel.
NORMALISE_TO_REF = True
REFERENCE = "mNG"        # control sample Name in the CSVs
N_LAST_READS = 4         # mNG level = mean of each well's last N reads (steady state)

# Line grouping. Any column of the CSV works, e.g. "Name", "DNA Template (nM)", "AHSL".
HUE = "Name"          # colour
STYLE = None          # line dash (e.g. "AHSL"); None = all solid
PALETTE = "tab10"     # seaborn palette name, or a list of colours
COLOR_OVERRIDES = {"mNG": "black"}   # fix colours for specific hue values

ERRORBAR = "sd"       # "sd", ("ci", 95), "se", or None for no band
SHARE_Y = True
Y_LIM = None          # e.g. (0, 4500); None = auto
X_LIM = None          # e.g. (0, 6)

FIGSIZE = (11, 4.8)
# Legend placement:
#   "shared" -> one legend under the figure (best when there are many lines)
#   "each"   -> a legend inside every panel at LEGEND_LOC (like the reference plot)
LEGEND_MODE = "shared"
LEGEND_LOC = "lower right"   # used when LEGEND_MODE = "each"
LEGEND_NCOL = 3              # used when LEGEND_MODE = "shared"
LEGEND_FONTSIZE = 10

# Fonts — set to match the RFU figure (matplotlib defaults: DejaVu Sans, 10 pt base)
FONT_FAMILY = "DejaVu Sans"
TICK_FONTSIZE = 10
TITLE_FONTSIZE = 12          # panel titles
LABEL_FONTSIZE = 10          # x / y axis labels
OUTFILE = "panels_seaborn.png"
DPI = 200

# =============================================================================


def load_panel(cfg):
    df = pd.read_csv(cfg["file"])

    # Filter sample names
    keep = pd.Series(True, index=df.index)
    if cfg.get("include"):
        keep = df["Name"].apply(lambda n: any(s in n for s in cfg["include"]))
    if cfg.get("exclude"):
        keep &= ~df["Name"].apply(lambda n: any(s in n for s in cfg["exclude"]))
    if cfg.get("extra"):
        keep |= df["Name"].isin(cfg["extra"])
    df = df[keep].copy()

    # y column
    if Y_DATA == "raw":
        df["y"] = df["Data_raw"] if "Data_raw" in df.columns else df["Data"]
    else:
        df["y"] = df["Data_normalized"]

    # Time in hours, aligned across replicate wells (they are read seconds apart)
    df["hours_raw"] = pd.to_timedelta(df["Time"]).dt.total_seconds() / 3600
    df["read_idx"] = df.groupby("Well").cumcount()
    df["hours"] = df.groupby("read_idx")["hours_raw"].transform("mean")

    # Handy grouping column
    df["AHSL"] = df["[AHSL] (uM)"].fillna(0).gt(0).map({True: "+ AHSL", False: "– AHSL"})
    return df


def main():
    sns.set_style("ticks")
    # seaborn's style switches the font list to Arial-first; force the publication font
    plt.rcParams.update({
        "font.family": "sans-serif",
        "font.sans-serif": [FONT_FAMILY],
        "font.size": TICK_FONTSIZE,
        "xtick.labelsize": TICK_FONTSIZE,
        "ytick.labelsize": TICK_FONTSIZE,
        "mathtext.fontset": "dejavusans",
        # nothing bold by default: only the \mathbf{...} part of the panel titles
        "font.weight": "normal",
        "axes.titleweight": "normal",
        "axes.labelweight": "normal",
        "figure.titleweight": "normal",
        "figure.labelweight": "normal",
    })
    data = [load_panel(p) for p in PANELS]

    if NORMALISE_TO_REF:
        # steady-state mNG level per file: last N reads per well, then mean over wells
        ref_means = []
        for df in data:
            ref = df[df["Name"] == REFERENCE].sort_values("hours_raw")
            ref_means.append(ref.groupby("Well").tail(N_LAST_READS)["y"].mean())
        common_ref = sum(ref_means) / len(ref_means)   # all files rescaled to this level
        for df, ref_mean in zip(data, ref_means):
            df["y"] = df["y"] * (common_ref / ref_mean)

    # Consistent colours across panels: one colour per hue value, shared by all panels
    hue_order = sorted(pd.concat(d[HUE] for d in data).unique(), key=str) if HUE else None
    if HUE:
        others = [h for h in hue_order if h not in COLOR_OVERRIDES]
        colors = dict(zip(others, sns.color_palette(PALETTE, len(others))))
        colors.update({h: c for h, c in COLOR_OVERRIDES.items() if h in hue_order})
    else:
        colors = None

    fig, axes = plt.subplots(1, len(PANELS), figsize=FIGSIZE, sharey=SHARE_Y, squeeze=False)
    axes = axes[0]

    for ax, cfg, df in zip(axes, PANELS, data):
        sns.lineplot(
            data=df, x="hours", y="y",
            hue=HUE, hue_order=[h for h in hue_order if h in set(df[HUE])] if HUE else None,
            palette=colors, style=STYLE,
            errorbar=ERRORBAR, ax=ax,
        )
        ax.set_title(cfg["title"], fontsize=TITLE_FONTSIZE, fontweight="normal")
        ax.set_xlabel("")
        ax.set_ylabel("")
        if X_LIM:
            ax.set_xlim(X_LIM)
        if ax.get_legend():
            if LEGEND_MODE == "each":
                sns.move_legend(ax, LEGEND_LOC, frameon=False, fontsize=LEGEND_FONTSIZE, title=None)
            else:
                ax.get_legend().remove()

    if Y_LIM:
        axes[0].set_ylim(Y_LIM)
    axes[0].set_ylabel(Y_LABEL, fontsize=LABEL_FONTSIZE, fontweight="normal")
    fig.supxlabel(X_LABEL, fontsize=LABEL_FONTSIZE, fontweight="normal")
    sns.despine(fig)

    if LEGEND_MODE == "shared" and (HUE or STYLE):
        # Collect unique entries across all panels
        seen = {}
        for ax in axes:
            for h, l in zip(*ax.get_legend_handles_labels()):
                seen.setdefault(l, h)
        fig.legend(seen.values(), seen.keys(), loc="lower center", ncol=LEGEND_NCOL,
                   frameon=False, fontsize=LEGEND_FONTSIZE, bbox_to_anchor=(0.5, -0.02))
        fig.tight_layout(rect=(0, 0.04 + 0.045 * -(-len(seen) // LEGEND_NCOL), 1, 1))
        fig.supxlabel(X_LABEL, fontsize=LABEL_FONTSIZE, fontweight="normal",
                      y=0.03 + 0.045 * -(-len(seen) // LEGEND_NCOL))
    else:
        fig.tight_layout()
    fig.savefig(OUTFILE, dpi=DPI, bbox_inches="tight")

if __name__ == "__main__":
    main()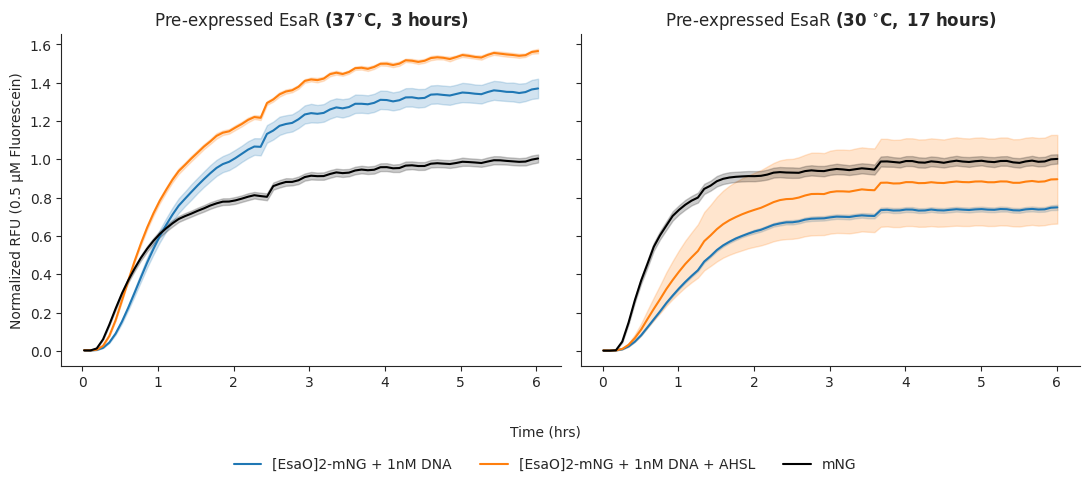
#!/usr/bin/env python3
"""
Side-by-side plate-reader kinetics with a shared y-axis (seaborn),
batch-corrected to the mNG (-EsaR) control. The mNG control is used for the
correction but is not drawn.

Edit the CONFIG block below, then run:
    python plot_panels_normalised.py
"""
import matplotlib.pyplot as plt
import pandas as pd
import seaborn as sns

# =============================================================================
# CONFIG — edit these
# =============================================================================

# One dict per panel, left -> right.
#   file    : CSV path
#   title   : panel title (mathtext $\mathbf{...}$ makes that part bold)
#   include : substring(s) a sample Name must contain to be plotted (None = all)
#   exclude : substring(s) that drop a sample Name (None = nothing dropped)
#   extra   : exact sample Name(s) loaded on top of `include`. Keep "mNG" here:
#             it is needed to compute the batch correction, then removed before plotting.
PANELS = [
    dict(file="normalized_samples_only.csv",
         title=r"Pre-expressed EsaR $\mathbf{(37^{\circ}C,\ 3\ hours)}$",
         include=["[EsaO]2-mNG"], exclude=None, extra=["mNG"]),
    dict(file="normalized_current_run.csv",
         title=r"Pre-expressed EsaR $\mathbf{(30\ ^{\circ}C,\ 17\ hours)}$",
         include=["[EsaO]2-mNG"], exclude=None, extra=["mNG"]),
]

SUPTITLE = "Pre-expressed EsaR comparison (Batch-corrected to - EsaR control signal)"
Y_LABEL = "Normalized RFU\n(0.5 µM Fluorescein)"
X_LABEL = "Time (hrs)"

# What to plot on y:
#   "normalized" -> Data_normalized (fluorescein-calibrated; comparable across days)
#   "raw"        -> raw counts (uses Data_raw if present, otherwise Data)
Y_DATA = "normalized"

# Batch correction to the mNG (-EsaR) control. Each file is multiplied by
# (common mNG level / that file's own mNG level), so the y-axis stays in
# normalized fluorescence units but PURE batch-to-batch offsets cancel.
REFERENCE = "mNG"        # control sample Name in the CSVs (corrected to, not plotted)
N_LAST_READS = 4         # mNG level = mean of each well's last N reads (steady state)

# Line grouping. Any column of the CSV works, e.g. "Name", "DNA Template (nM)", "AHSL".
HUE = "Name"          # colour
STYLE = None          # line dash (e.g. "AHSL"); None = all solid
PALETTE = "tab10"     # seaborn palette name, or a list of colours

ERRORBAR = "sd"       # "sd", ("ci", 95), "se", or None for no band
SHARE_Y = True
Y_LIM = None          # e.g. (0, 4500); None = auto
X_LIM = None          # e.g. (0, 6)

FIGSIZE = (11, 4.8)
# Legend placement:
#   "shared" -> one legend under the figure (best when there are many lines)
#   "each"   -> a legend inside every panel at LEGEND_LOC (like the reference plot)
LEGEND_MODE = "shared"
LEGEND_LOC = "lower right"   # used when LEGEND_MODE = "each"
LEGEND_NCOL = 3              # used when LEGEND_MODE = "shared"
LEGEND_FONTSIZE = 10

# Fonts — set to match the RFU figure (matplotlib defaults: DejaVu Sans, 10 pt base)
FONT_FAMILY = "DejaVu Sans"
TICK_FONTSIZE = 10
TITLE_FONTSIZE = 12          # panel titles
LABEL_FONTSIZE = 14          # x / y axis labels
SUPTITLE_FONTSIZE = 16
Y_LABELPAD = 14              # distance (pt) between the y label and the tick labels
OUTFILE = "panels_seaborn_mNG_normalised.png"
DPI = 200

# =============================================================================


def load_panel(cfg):
    df = pd.read_csv(cfg["file"])

    # Filter sample names
    keep = pd.Series(True, index=df.index)
    if cfg.get("include"):
        keep = df["Name"].apply(lambda n: any(s in n for s in cfg["include"]))
    if cfg.get("exclude"):
        keep &= ~df["Name"].apply(lambda n: any(s in n for s in cfg["exclude"]))
    if cfg.get("extra"):
        keep |= df["Name"].isin(cfg["extra"])
    df = df[keep].copy()

    # y column
    if Y_DATA == "raw":
        df["y"] = df["Data_raw"] if "Data_raw" in df.columns else df["Data"]
    else:
        df["y"] = df["Data_normalized"]

    # Time in hours, aligned across replicate wells (they are read seconds apart)
    df["hours_raw"] = pd.to_timedelta(df["Time"]).dt.total_seconds() / 3600
    df["read_idx"] = df.groupby("Well").cumcount()
    df["hours"] = df.groupby("read_idx")["hours_raw"].transform("mean")

    # Handy grouping column
    df["AHSL"] = df["[AHSL] (uM)"].fillna(0).gt(0).map({True: "+ AHSL", False: "– AHSL"})
    return df


def normalise_to_reference(data):
    """Rescale y so every file's mNG (-EsaR) steady-state level matches the average level."""
    ref_means = []
    for df in data:
        ref = df[df["Name"] == REFERENCE].sort_values("hours_raw")
        ref_means.append(ref.groupby("Well").tail(N_LAST_READS)["y"].mean())
    common_ref = sum(ref_means) / len(ref_means)

    out = []
    for df, ref_mean in zip(data, ref_means):
        df = df.copy()
        df["y"] = df["y"] * (common_ref / ref_mean)
        out.append(df)
    return out


def main():
    sns.set_style("ticks")
    # seaborn's style switches the font list to Arial-first; force the publication font
    plt.rcParams.update({
        "font.family": "sans-serif",
        "font.sans-serif": [FONT_FAMILY],
        "font.size": TICK_FONTSIZE,
        "xtick.labelsize": TICK_FONTSIZE,
        "ytick.labelsize": TICK_FONTSIZE,
        "mathtext.fontset": "dejavusans",
        # nothing bold by default: only the \mathbf{...} part of the panel titles
        "font.weight": "normal",
        "axes.titleweight": "normal",
        "axes.labelweight": "normal",
        "figure.titleweight": "normal",
        "figure.labelweight": "normal",
    })

    # Load (mNG included), batch-correct, then drop the mNG control before plotting
    data = [load_panel(p) for p in PANELS]
    data = normalise_to_reference(data)
    data = [df[df["Name"] != REFERENCE].copy() for df in data]

    # Consistent colours across panels: one colour per hue value, shared by all panels
    hue_order = sorted(pd.concat(d[HUE] for d in data).unique(), key=str) if HUE else None
    colors = dict(zip(hue_order, sns.color_palette(PALETTE, len(hue_order)))) if HUE else None

    fig, axes = plt.subplots(1, len(PANELS), figsize=FIGSIZE, sharey=SHARE_Y, squeeze=False)
    axes = axes[0]

    for ax, cfg, df in zip(axes, PANELS, data):
        sns.lineplot(
            data=df, x="hours", y="y",
            hue=HUE, hue_order=[h for h in hue_order if h in set(df[HUE])] if HUE else None,
            palette=colors, style=STYLE,
            errorbar=ERRORBAR, ax=ax,
        )
        ax.set_title(cfg["title"], fontsize=TITLE_FONTSIZE, fontweight="normal")
        ax.set_xlabel("")
        ax.set_ylabel("")
        if X_LIM:
            ax.set_xlim(X_LIM)
        if ax.get_legend():
            if LEGEND_MODE == "each":
                sns.move_legend(ax, LEGEND_LOC, frameon=False, fontsize=LEGEND_FONTSIZE, title=None)
            else:
                ax.get_legend().remove()

    if Y_LIM:
        axes[0].set_ylim(Y_LIM)
    axes[0].set_ylabel(Y_LABEL, fontsize=LABEL_FONTSIZE, fontweight="normal", labelpad=Y_LABELPAD)
    fig.supxlabel(X_LABEL, fontsize=LABEL_FONTSIZE, fontweight="normal")
    fig.suptitle(SUPTITLE, fontsize=SUPTITLE_FONTSIZE, fontweight="normal")
    sns.despine(fig)

    if LEGEND_MODE == "shared" and (HUE or STYLE):
        # Collect unique entries across all panels
        seen = {}
        for ax in axes:
            for h, l in zip(*ax.get_legend_handles_labels()):
                seen.setdefault(l, h)
        fig.legend(seen.values(), seen.keys(), loc="lower center", ncol=LEGEND_NCOL,
                   frameon=False, fontsize=LEGEND_FONTSIZE, bbox_to_anchor=(0.5, -0.02))
        fig.tight_layout(rect=(0, 0.04 + 0.045 * -(-len(seen) // LEGEND_NCOL), 1, 1))
        fig.supxlabel(X_LABEL, fontsize=LABEL_FONTSIZE, fontweight="normal",
                      y=0.03 + 0.045 * -(-len(seen) // LEGEND_NCOL))
    else:
        fig.tight_layout()
    fig.savefig(OUTFILE, dpi=DPI, bbox_inches="tight")
    plt.show()


if __name__ == "__main__":
    main()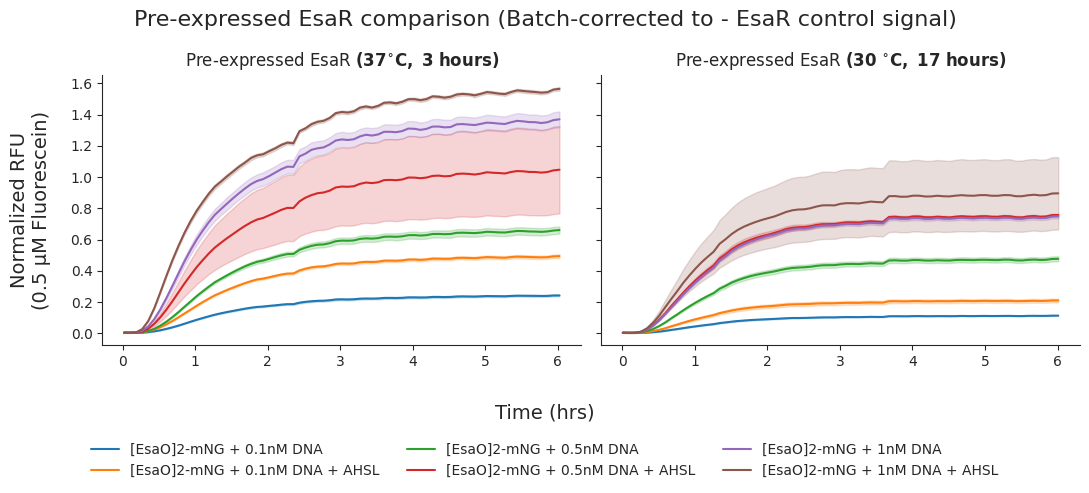
#!/usr/bin/env python3
"""
Steady-state AHSL fold induction (+AHSL / −AHSL) per DNA concentration,
for each EsaR preparation, plotted as grouped bars.

Edit the CONFIG block, then run:
    python plot_fold_change.py
"""
import matplotlib.pyplot as plt
import pandas as pd
import seaborn as sns

# =============================================================================
# CONFIG
# =============================================================================
DATASETS = {
    "Pre-expressed EsaR (30°C, 17 hours)": "normalized_current_run.csv",
    "Pre-expressed EsaR (37°C, 3 hours)": "normalized_samples_only.csv",
}
CONSTRUCT = "[EsaO]2-mNG"
DNA_CONCS = ["0.1", "0.5", "1"]   # as written in the sample names, e.g. "0.1nM"
N_LAST = 10                       # rows used for the steady-state mean (see note below)
Y_COL = "Data_normalized"         # fold change is identical with raw data (constant scale per file)

TITLE = f"Steady-state AHSL fold induction"
X_LABEL = "DNA concentration (nM)"
Y_LABEL = "RFU Fold change (+AHSL / −AHSL)"
PALETTE = ["tab:orange", "tab:blue"]
FIGSIZE = (6, 5)
OUTFILE = "fold_change.png"
# =============================================================================


def steady_state_fold_change(df, base_name, ahsl_name, n_last=N_LAST):
    # Note: nlargest pools rows from all replicate wells of a Name, so with 3 wells
    # n_last=10 covers roughly the last 3–4 reads (~15–20 min), not 10 time points.
    tail = df.groupby("Name").apply(
        lambda g: g.nlargest(n_last, "Time_hrs")[Y_COL].mean(), include_groups=False
    )
    return tail[ahsl_name] / tail[base_name]


rows = []
for label, path in DATASETS.items():
    df = pd.read_csv(path)
    df["Time_hrs"] = pd.to_timedelta(df["Time"]).dt.total_seconds() / 3600
    for conc in DNA_CONCS:
        base = f"{CONSTRUCT} + {conc}nM DNA"
        fc = steady_state_fold_change(df, base, base + " + AHSL")
        rows.append({"EsaR prep": label, "DNA_conc_nM": float(conc), "Fold_change": fc})

fold_summary = pd.DataFrame(rows)
#print(fold_summary.pivot(index="DNA_conc_nM", columns="EsaR prep", values="Fold_change").round(2))

fig, ax = plt.subplots(figsize=FIGSIZE)
sns.barplot(data=fold_summary, x="DNA_conc_nM", y="Fold_change", hue="EsaR prep",
            palette=PALETTE, ax=ax)
ax.set(xlabel=X_LABEL, ylabel=Y_LABEL)
ax.set_title(TITLE)
ax.axhline(1, color="grey", linestyle="--", linewidth=1)
ax.set_ylim(1, 2.25)
ax.legend(title=None, frameon=False, loc="upper right")

sns.despine(fig)
fig.tight_layout()
fig.savefig(OUTFILE, dpi=200, bbox_inches="tight")
plt.show()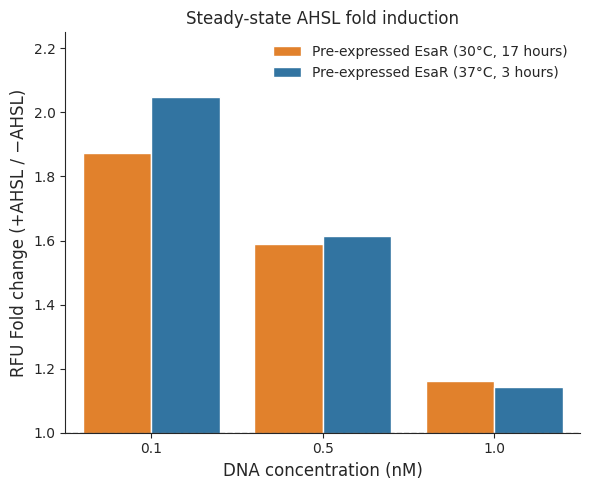
preps = list(DATASETS.keys())   # one panel per EsaR prep, in CONFIG order

fig, (ax1, ax2) = plt.subplots(1, 2, figsize=(10, 5), sharey=True)

# --- Panel 1: first EsaR prep ---
subset_1 = fold_summary[fold_summary["EsaR prep"] == preps[0]]
sns.barplot(data=subset_1, x="DNA_conc_nM", y="Fold_change", color=PALETTE[0], ax=ax1)
ax1.set(title=preps[0], xlabel="", ylabel="")
ax1.axhline(1, color="grey", linestyle="--", linewidth=1)

# --- Panel 2: second EsaR prep ---
subset_2 = fold_summary[fold_summary["EsaR prep"] == preps[1]]
sns.barplot(data=subset_2, x="DNA_conc_nM", y="Fold_change", color=PALETTE[1], ax=ax2)
ax2.set(title=preps[1], xlabel="", ylabel="")
ax2.axhline(1, color="grey", linestyle="--", linewidth=1)

ax1.set_ylim(1, 2.25)   # sharey=True applies this to both panels

fig.supxlabel(X_LABEL)
fig.supylabel(Y_LABEL)

sns.despine(fig)
fig.tight_layout()
fig.savefig(OUTFILE, dpi=200, bbox_inches="tight")
plt.show()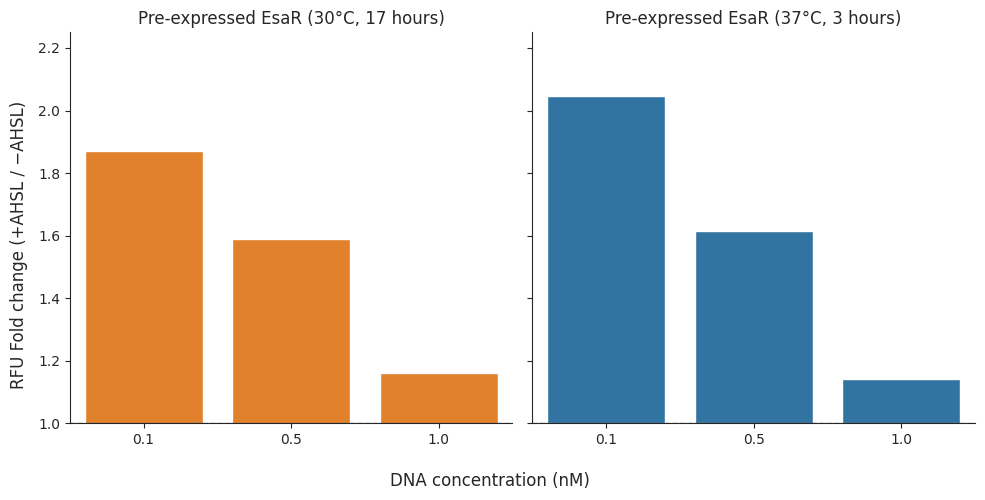
import matplotlib.pyplot as plt
import pandas as pd
import seaborn as sns

# =============================================================================
# CONFIG
# =============================================================================
DATASETS = {
    "Pre-expressed EsaR (30°C, 17 hours)": "normalized_current_run.csv",
    "Pre-expressed EsaR (37°C, 3 hours)": "normalized_samples_only.csv",
}
CONSTRUCT = "[EsaO]2-mNG"
DNA_CONCS = ["0.1", "0.5", "1"]
REFERENCE = "mNG"
N_LAST_READS = 4
Y_COL = "Data_normalized"

PALETTE = ["tab:orange", "tab:blue"]

FONT_FAMILY = "DejaVu Sans"
BASE_FONTSIZE = 10
TITLE_FONTSIZE = 12
LABEL_FONTSIZE = 12

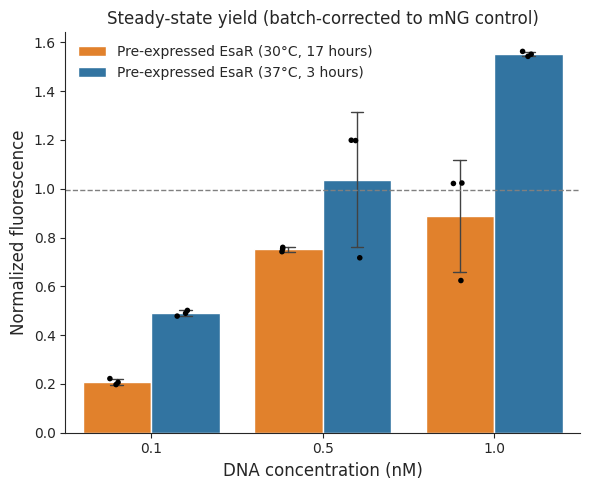
TITLE = "Steady-state yield (batch-corrected to mNG control)"
X_LABEL = "DNA concentration (nM)"
Y_LABEL = "Normalized fluorescence"
ERRORBAR = "sd"
SHOW_POINTS = True
FIGSIZE = (6, 5)
OUTFILE = "steady_state_yield_batch_corrected.png"
DPI = 200
# =============================================================================

plt.rcParams.update({
    "font.family": "sans-serif",
    "font.sans-serif": [FONT_FAMILY],
    "font.size": BASE_FONTSIZE,
    "axes.titlesize": TITLE_FONTSIZE,
    "axes.labelsize": LABEL_FONTSIZE,
    "legend.fontsize": BASE_FONTSIZE,
})
PREP_COLORS = dict(zip(DATASETS, PALETTE))


def steady_state_yield_per_well(path, n_reads=N_LAST_READS):
    df = pd.read_csv(path)
    df["Time_hrs"] = pd.to_timedelta(df["Time"]).dt.total_seconds() / 3600
    return (df.sort_values("Time_hrs").groupby(["Name", "Well"])
              .tail(n_reads).groupby(["Name", "Well"])[Y_COL].mean().reset_index())


# ----------------------------------------------------------------------------
# Batch-correction factors from the mNG (-EsaR) control
# ----------------------------------------------------------------------------
wells_by_prep = {label: steady_state_yield_per_well(path) for label, path in DATASETS.items()}
ref_means = pd.Series({label: w.loc[w["Name"] == REFERENCE, Y_COL].mean()
                       for label, w in wells_by_prep.items()})
common_ref = ref_means.mean()                 # all files are rescaled to this mNG level
scale = common_ref / ref_means                # multiplicative factor per file

print("mNG reference mean per file:\n", ref_means.round(3).to_string())
print(f"Common mNG level: {common_ref:.3f}")
print("Scale factors:\n", scale.round(3).to_string())

# ----------------------------------------------------------------------------
# Compute corrected per-well values
# ----------------------------------------------------------------------------
rows = []
ref_rows = []
for label, wells in wells_by_prep.items():
    for v in wells.loc[wells["Name"] == REFERENCE, Y_COL]:
        ref_rows.append({"EsaR prep": label, "Raw": v, "Corrected": v * scale[label]})

    for conc in DNA_CONCS:
        name = f"{CONSTRUCT} + {conc}nM DNA + AHSL"
        for v in wells.loc[wells["Name"] == name, Y_COL]:
            rows.append({"EsaR prep": label, "DNA_conc_nM": float(conc),
                         "Yield": v * scale[label]})

yield_wells = pd.DataFrame(rows)
ref_wells = pd.DataFrame(ref_rows)

# ----------------------------------------------------------------------------
# Figure 1: batch-corrected yield
# ----------------------------------------------------------------------------
fig, ax = plt.subplots(figsize=FIGSIZE)
kw = dict(data=yield_wells, x="DNA_conc_nM", y="Yield", hue="EsaR prep",
          hue_order=list(DATASETS), ax=ax)
sns.barplot(**kw, palette=PREP_COLORS, errorbar=ERRORBAR, capsize=0.15,
            err_kws={"linewidth": 1})
if SHOW_POINTS:
    sns.stripplot(**kw, palette={p: "black" for p in DATASETS},
                  dodge=True, size=4, legend=False)

ax.axhline(common_ref, color="grey", linestyle="--", linewidth=1)   # mNG (-EsaR) level
ax.set(xlabel=X_LABEL, ylabel=Y_LABEL)
ax.set_title(TITLE)
ax.legend(title=None, frameon=False)

sns.despine(fig)
fig.tight_layout()
fig.savefig(OUTFILE, dpi=DPI, bbox_inches="tight")
plt.show()

# ----------------------------------------------------------------------------
# Figure 2: mNG control before vs after batch correction
# ----------------------------------------------------------------------------
fig2, (axA, axB) = plt.subplots(1, 2, figsize=(7, 4.5), sharey=True)
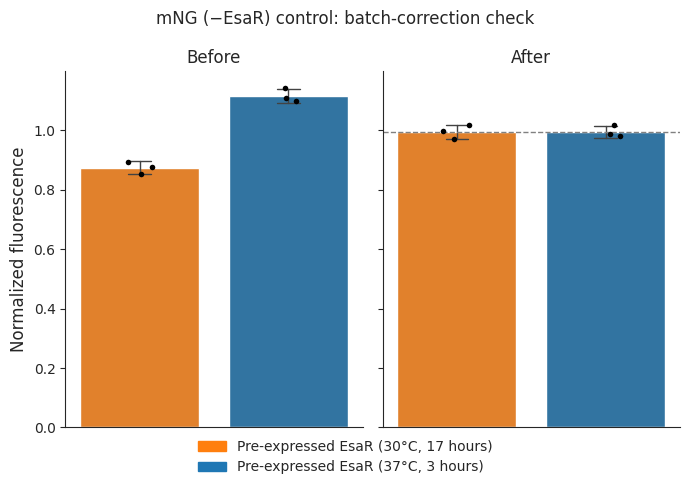
fig2.suptitle("mNG (−EsaR) control: batch-correction check")

for ax_, col, title in [(axA, "Raw", "Before"), (axB, "Corrected", "After")]:
    sns.barplot(data=ref_wells, x="EsaR prep", y=col, hue="EsaR prep",
                order=list(DATASETS), hue_order=list(DATASETS), palette=PREP_COLORS,
                errorbar=ERRORBAR, capsize=0.15, err_kws={"linewidth": 1},
                legend=False, ax=ax_)
    sns.stripplot(data=ref_wells, x="EsaR prep", y=col, order=list(DATASETS),
                  color="black", size=4, ax=ax_)
    ax_.set(title=title, xlabel="", ylabel="")
    ax_.set_xticks([])

axA.set_ylabel(Y_LABEL)
axB.axhline(common_ref, color="grey", linestyle="--", linewidth=1)

handles = [plt.Rectangle((0, 0), 1, 1, color=PREP_COLORS[p]) for p in DATASETS]
fig2.legend(handles, list(DATASETS), loc="lower center", ncol=1,
            frameon=False, bbox_to_anchor=(0.5, -0.08))

sns.despine(fig2)
fig2.tight_layout()
fig2.savefig("mNG_control_check.png", dpi=DPI, bbox_inches="tight")
plt.show()
mNG reference mean per file:
Pre-expressed EsaR (30°C, 17 hours) 0.87
Pre-expressed EsaR (37°C, 3 hours) 1.11
Common mNG level: 0.994
Scale factors:
Pre-expressed EsaR (30°C, 17 hours) 1.14
Pre-expressed EsaR (37°C, 3 hours) 0.89
import matplotlib.pyplot as plt
import pandas as pd
import seaborn as sns

# =============================================================================
# CONFIG
# =============================================================================
DATASETS = {
    "Pre-expressed EsaR (30°C, 17 hours)": "normalized_current_run.csv",
    "Pre-expressed EsaR (37°C, 3 hours)": "normalized_samples_only.csv",
}
CONSTRUCT = "[EsaO]2-mNG"
DNA_CONCS = ["0.1", "0.5", "1"]
REFERENCE = "mNG"
N_LAST_READS = 4
Y_COL = "Data_normalized"

PALETTE = ["tab:orange", "tab:blue"]

FONT_FAMILY = "DejaVu Sans"
BASE_FONTSIZE = 10
TITLE_FONTSIZE = 12
LABEL_FONTSIZE = 12

TITLE = "End-point Fluorescence (batch-corrected)"
X_LABEL = "DNA concentration (nM)"
Y_LABEL = "Normalized RFU"
ERRORBAR = "sd"
SHOW_POINTS = True
FIGSIZE = (6, 5)
OUTFILE = "steady_state_yield_batch_corrected.png"
DPI = 200
# =============================================================================

plt.rcParams.update({
    "font.family": "sans-serif",
    "font.sans-serif": [FONT_FAMILY],
    "font.size": BASE_FONTSIZE,
    "axes.titlesize": TITLE_FONTSIZE,
    "axes.labelsize": LABEL_FONTSIZE,
    "legend.fontsize": BASE_FONTSIZE,
})
PREP_COLORS = dict(zip(DATASETS, PALETTE))


def steady_state_yield_per_well(path, n_reads=N_LAST_READS):
    df = pd.read_csv(path)
    df["Time_hrs"] = pd.to_timedelta(df["Time"]).dt.total_seconds() / 3600
    return (df.sort_values("Time_hrs").groupby(["Name", "Well"])
              .tail(n_reads).groupby(["Name", "Well"])[Y_COL].mean().reset_index())


# ----------------------------------------------------------------------------
# Batch-correction factors from the mNG (-EsaR) control
# ----------------------------------------------------------------------------
wells_by_prep = {label: steady_state_yield_per_well(path) for label, path in DATASETS.items()}
ref_means = pd.Series({label: w.loc[w["Name"] == REFERENCE, Y_COL].mean()
                       for label, w in wells_by_prep.items()})
scale = ref_means.mean() / ref_means   # rescale every file to the average mNG level

# ----------------------------------------------------------------------------
# Corrected per-well values
# ----------------------------------------------------------------------------
rows = []
for label, wells in wells_by_prep.items():
    for conc in DNA_CONCS:
        name = f"{CONSTRUCT} + {conc}nM DNA + AHSL"
        for v in wells.loc[wells["Name"] == name, Y_COL]:
            rows.append({"EsaR prep": label, "DNA_conc_nM": float(conc),
                         "Yield": v * scale[label]})

yield_wells = pd.DataFrame(rows)

# ----------------------------------------------------------------------------
# Plot
# ----------------------------------------------------------------------------
fig, ax = plt.subplots(figsize=FIGSIZE)
kw = dict(data=yield_wells, x="DNA_conc_nM", y="Yield", hue="EsaR prep",
          hue_order=list(DATASETS), ax=ax)
sns.barplot(**kw, palette=PREP_COLORS, errorbar=ERRORBAR, capsize=0.15,
            err_kws={"linewidth": 1})
if SHOW_POINTS:
    sns.stripplot(**kw, palette={p: "black" for p in DATASETS},
                  dodge=True, size=4, legend=False)

ax.set(xlabel=X_LABEL, ylabel=Y_LABEL)
ax.set_title(TITLE)
ax.legend(title=None, frameon=False)

sns.despine(fig)
fig.tight_layout()
fig.savefig(OUTFILE, dpi=DPI, bbox_inches="tight")
plt.show()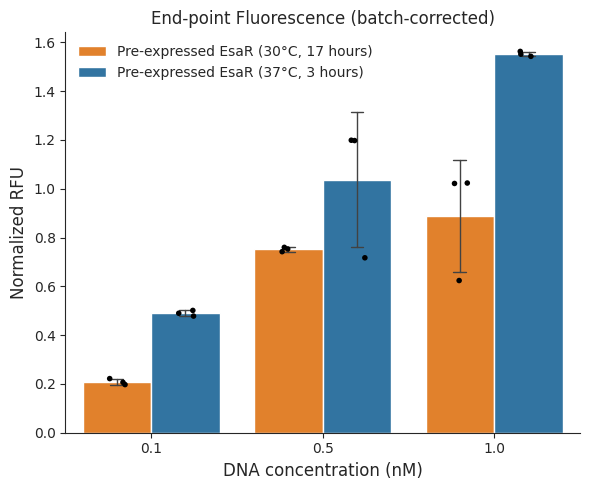
If you want to change the time window over which you calculate the average, you can use the window argument:
# data = data.normalize('10 uM HPTS', window=pd.Timedelta("2.5h"))Kinetic Analysis
See the DevNote on kinetic analysis for more details.
Metrics extracted:
Maximum velocity: Maximum rate of fluorescence increase (slope at inflection point)
Lag time: Time to reach the exponential phase
Steady-state: Final fluorescence level
Time-to-completion: Time it takes to reach 95% of asymptote
Drift: Rate of signal decay or increase after steady-state
R²: Goodness of fit; “Good Fit” is
Trueif
# Perform kinetic analysis using sigmoid_drift model
kinetics = data.fit_kinetics()
[07/16/26 17:29:20] INFO Calculating Kinetics analysis.py:223
kinetics.summaryVisualize Fits
g = kinetics.plot(col="Well")
# g = kinetics.plot() # call this to visualize across replicates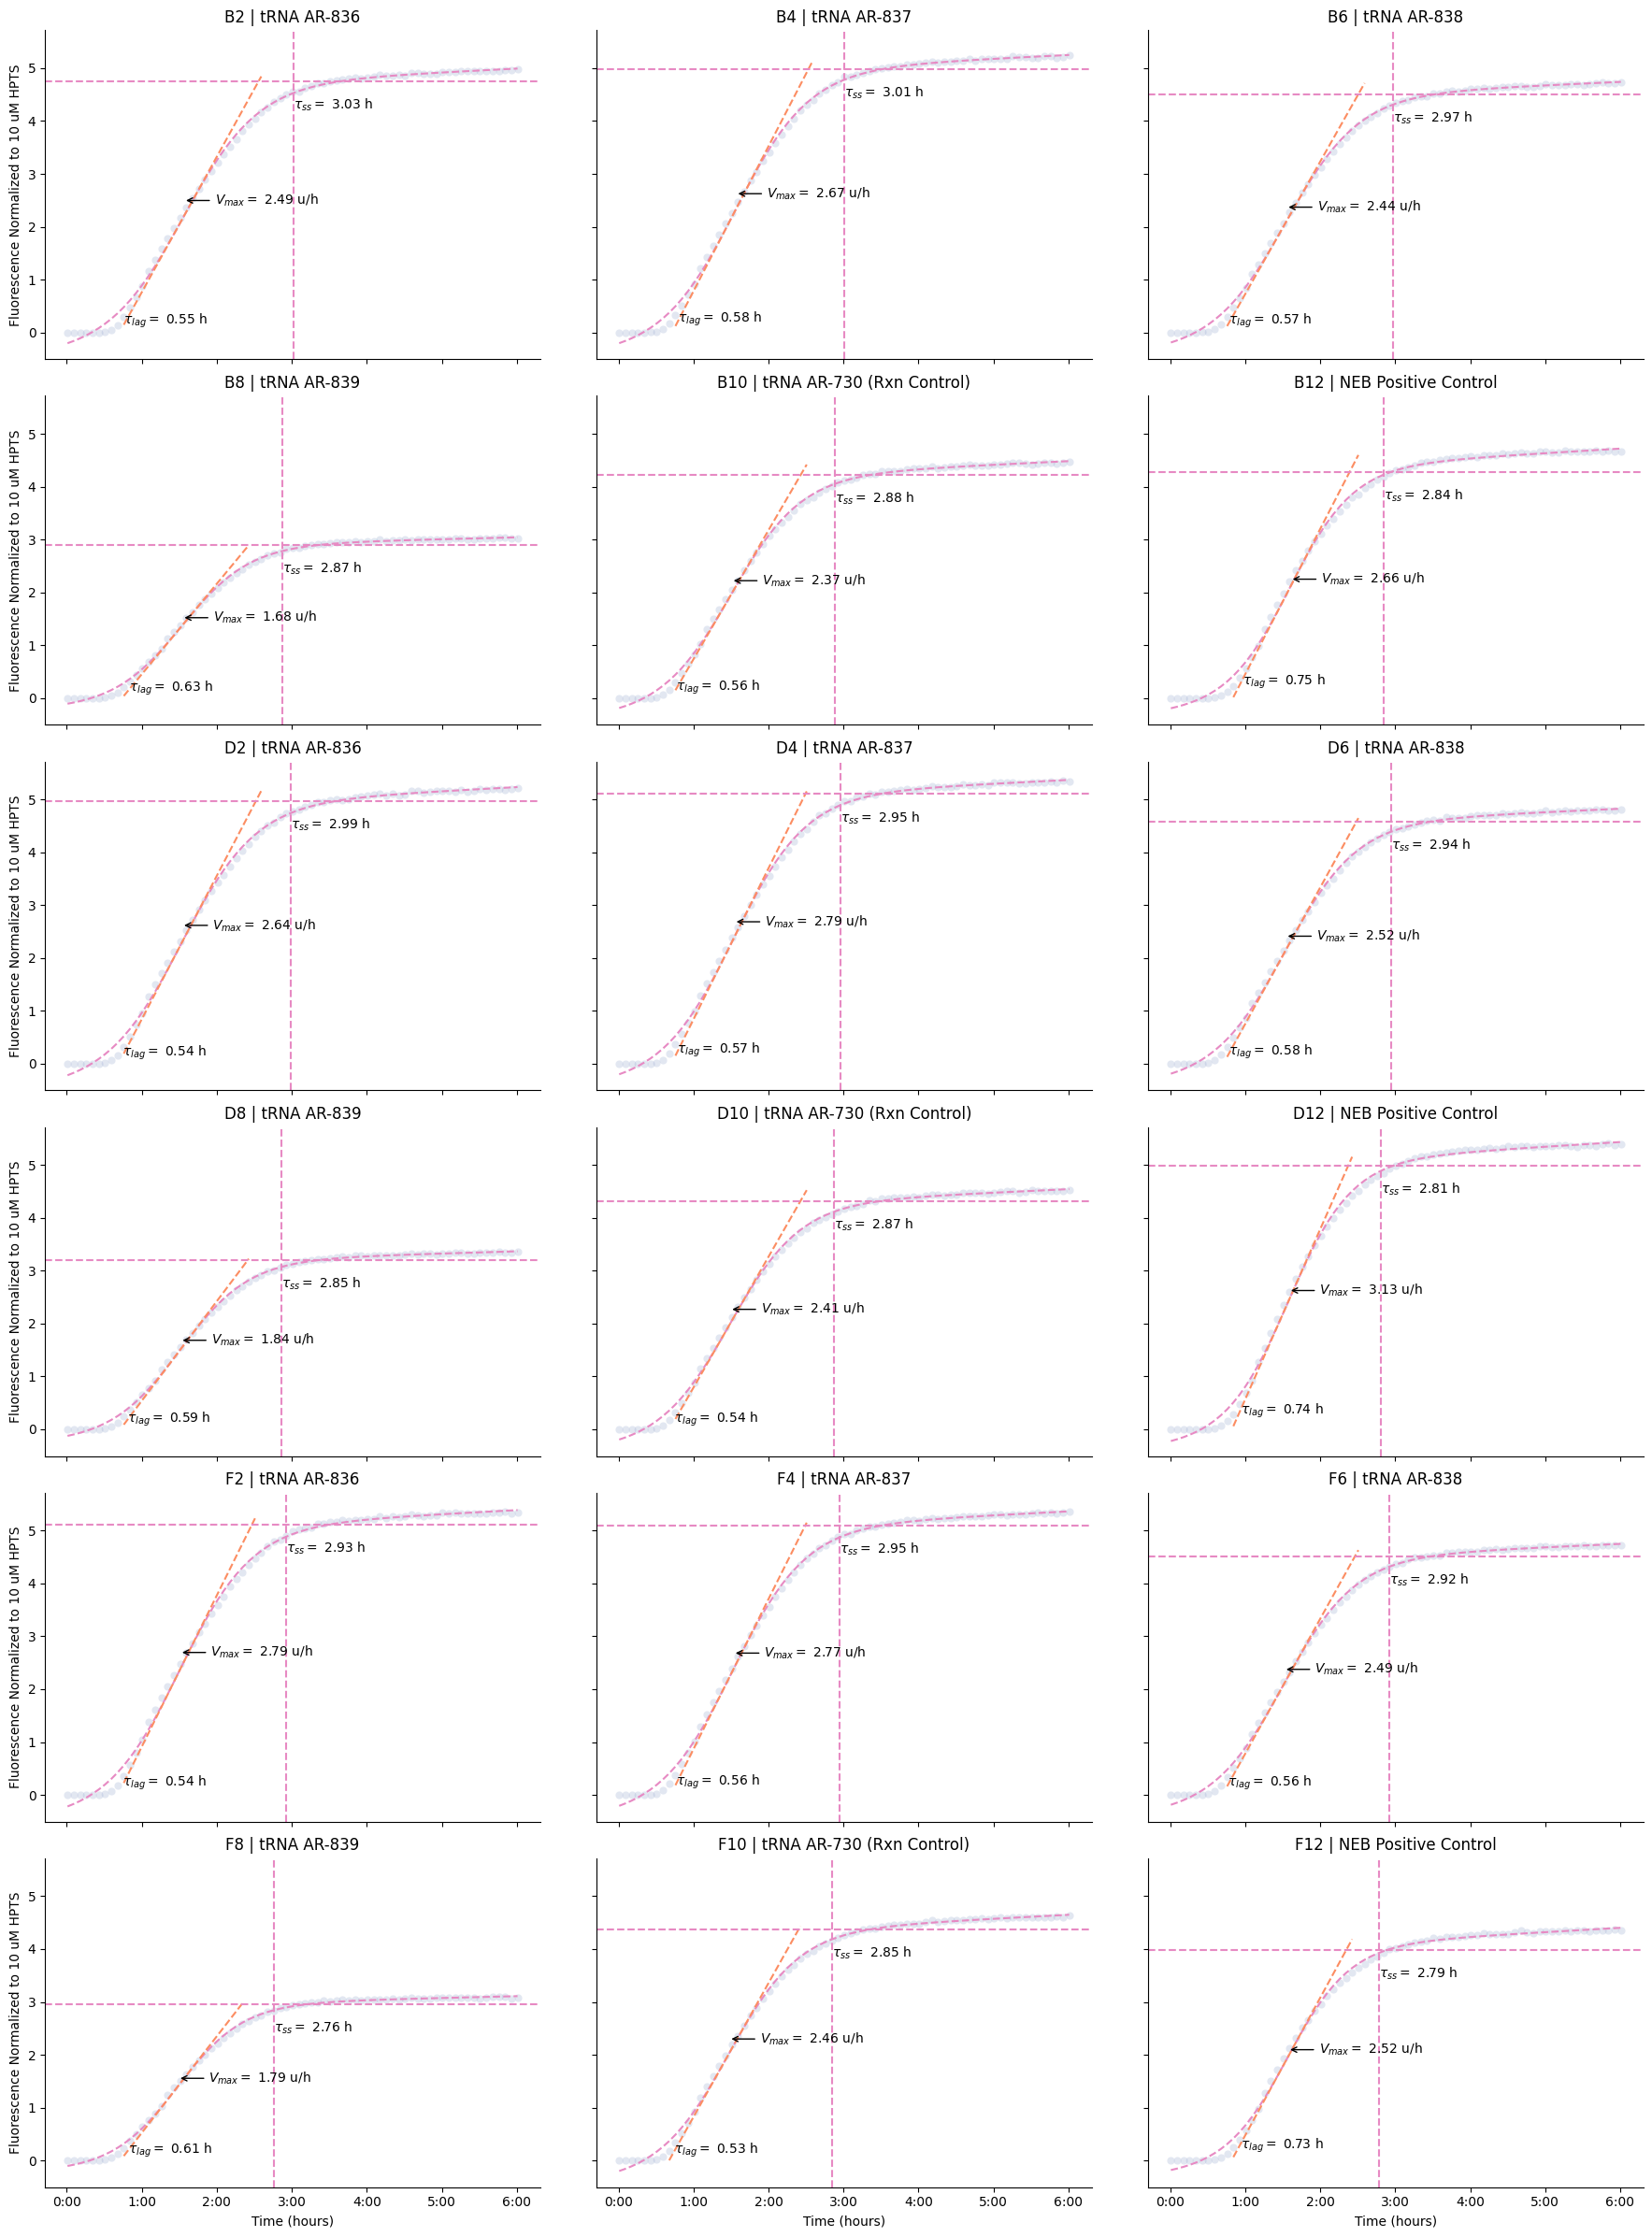
Summary Plots
g = kinetics.plot_summary()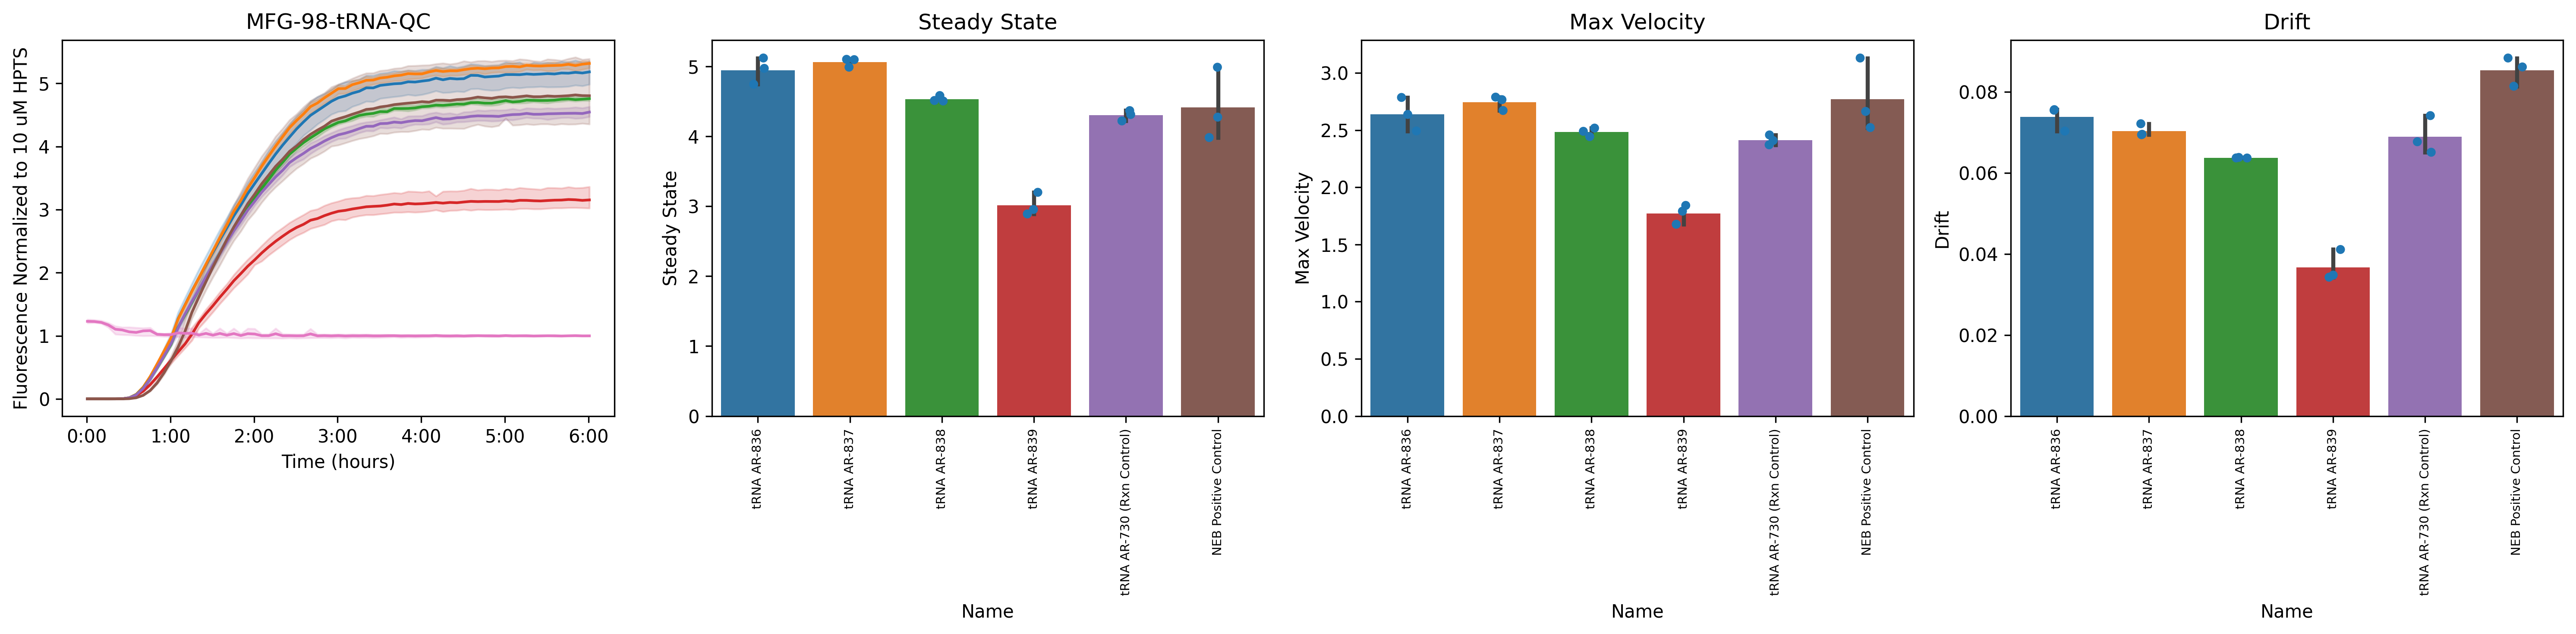
Key Metrics Explained
1. Steady-State Level (Steady State, Data)
The final fluorescence value reached by the reaction
Represents the total amount of protein produced
Higher values indicate greater expression yield
2. Maximum Velocity (Velocity, Max)
The steepest slope of the fluorescence curve (at the inflection point)
Units: RFU per second
Reflects the peak rate of protein synthesis
Sensitive to enzyme activity, substrate availability, and reaction conditions
3. Lag Time (Lag, Time)
Time before exponential fluorescence increase begins
May reflect time for ribosome assembly or initial translation steps
Shorter lag times suggest faster reaction initiation
4. Drift (Fit, drift)
Rate of fluorescence change after reaching steady-state
Positive drift: continued synthesis or aggregation
Negative drift: photobleaching, protein degradation, or quenching
Units: RFU per second
5. R² Value (Fit, R^2)
Goodness of fit (0 to 1, higher is better)
R² > 0.98 indicates excellent fit
Poor fits may indicate noisy data, overflow errors, or non-sigmoid kinetics
Tips and Troubleshooting
Overflow errors: Wells with
OVRFLWorNaNvalues are automatically excluded from fittingPoor fits (low R²): Inspect raw curves for anomalies (bubbles, evaporation, pipetting errors)
Drift: Sometimes seen in kinetics curves; use
sigmoid_driftmodelMultiple replicates: Always include technical replicates and report error bars
Comparing conditions: Normalize or blank data consistently across all samples
Next Steps
Export kinetics results:
pr.export_kinetics(kinetics, 'results.csv')Statistical analysis: Use
scipy.statsorstatsmodelsfor ANOVA/t-testsParameter optimization: Vary Mg²⁺, K⁺, or other conditions to maximize Vmax or steady-state
Mechanistic modeling: Fit ODE models to extract biological rate constants