1. Setup and Data Retrieval — Group B, Jul 23
Analyze time-series data from platereader experiments.
1. Setup and Data Retrieval — Group B, Jul 23
try:
    import cdk
    print("CDK already installed, skipping installation and restart.")
except ImportError:
    !pip install nucleus-cdk==0.6.0rc1 -q
    print("\nInstallation complete. Restarting runtime to refresh dependencies...")
    import os
    os._exit(0)
CDK already installed, skipping installation and restart.
%%writefile drive_utils.py
import os
import re
import gdown

def get_drive_file_id(url):
    """Extracts file ID from a Google Drive URL."""
    match = re.search(r'/d/([a-zA-Z0-9_-]+)', url)
    if match:
        return match.group(1)
    return None

def download_from_drive(files_info, destination_dir):
    """
    Downloads files from Google Drive.

    Args:
        files_info (list): List of dicts with 'url' and 'filename'.
        destination_dir (str): Local path to save files.
    Returns:
        dict: Mapping of filenames to local paths.
    """
    if not os.path.exists(destination_dir):
        os.makedirs(destination_dir)

    paths = {}
    for item in files_info:
        url = item['url']
        filename = item['filename']
        dest = os.path.join(destination_dir, filename)
        file_id = get_drive_file_id(url)

        if file_id:
            gdown.download(id=file_id, output=dest, quiet=True)
        else:
            gdown.download(url, output=dest, quiet=True)

        paths[filename] = dest
    return paths
Writing drive_utils.py
import os
import re
import sys
import shutil
import pandas as pd
import seaborn as sns
import matplotlib.pyplot as plt

# Custom CDK and utility imports
from cdk import logging
from cdk.instruments import platereader as pr
from drive_utils import download_from_drive

# Initialize logging
log = logging.setup_logging(logging.INFO)

print("Setup and imports consolidated successfully.")
INFO:cdk.logging:Logging initialized
Setup and imports consolidated successfully.
# Define file information
files_to_download = [
    {
        "url": "https://drive.google.com/file/d/1oJTTNOlV_ZL-vgCKI7gukyuKDQphuUb2/view?usp=sharing", # Replace the link with your data file link. Make sure the file permissions are set to 'Anyone with a link' can 'view'.
        "filename": "raw_data.txt"
    },
    {
        "url": "https://drive.google.com/file/d/1ywYHIGPjkor5DC1RYZc7b5JUk-AR4PL9/view?usp=sharing", # Replace the link with your platemap file link. Make sure the file permissions are set to 'Anyone with a link' can 'view'.
        "filename": "platemap.csv"
    }
]

# Local destination
local_data_dir = "/content/data"

# Execute simplified download
downloaded_paths = download_from_drive(files_to_download, local_data_dir)

# Update global variables for downstream use
data_file = downloaded_paths["raw_data.txt"]
platemap_file = downloaded_paths["platemap.csv"]

print(f"Files ready at:\n- Data: {data_file}\n- Platemap: {platemap_file}")
Files ready at:
- Data: /content/data/raw_data.txt
- Platemap: /content/data/platemap.csv
2. Load and Analyze Data
# Load data
result = pr.load_platereader_data(
    data_file=data_file,
    platemap_file=platemap_file,
    platereader="biotek" # options: "biotek"
)
INFO:cdk.instruments.platereader.loaders.biotek:BioTek optics source (filter/monochromator) is inferred and may be incorrect.
INFO:cdk.instruments.platereader.loaders.biotek:Found 1 plate blocks
INFO:cdk.instruments.platereader.loaders.biotek:Parsing plate block 1
INFO:cdk.instruments.platereader.loaders.biotek:Read metadata section, found 1 read block(s).
WARNING:cdk.instruments.platereader.loaders.biotek:Data column contains non-numeric values.
INFO:cdk.instruments.platereader.loaders.biotek:Parsed 2 segment(s) successfully.
INFO:cdk.instruments.platereader.loaders.biotek:Found 0 segment(s) that could not be associated with existing read data.
The output is a list of PlateReaderResult objects; if you did more than one read on the plate reader, the results will be in separate objects.
print(result)PlateReaderResult with the following 2 blocks:
0: (1022, 35) kinetic read with reads: GFP:485,528 (Fluorescence) (Plate 'Plate 1')
1: (56, 33) endpoint read with reads: Max V [GFP:485,528] (Fluorescence), R-Squared [GFP:485,528] (Fluorescence), t at Max V [GFP:485,528] (Fluorescence), Lagtime [GFP:485,528] (Fluorescence) (Plate 'Plate 1')
Here there were two reads with different gains but the same excitation/emission spectrum, on one plate. If we want just the GFP-Gext read, this corresponds to block index 1, so we can extract that block by indexing:
desired_index = 0
data = result[desired_index]
data
(1022, 35) kinetic read with reads: GFP:485,528 (Fluorescence)Plot Raw Curves
data.plot(style='Type')<seaborn.axisgrid.FacetGrid at 0x7bb03956d4f0>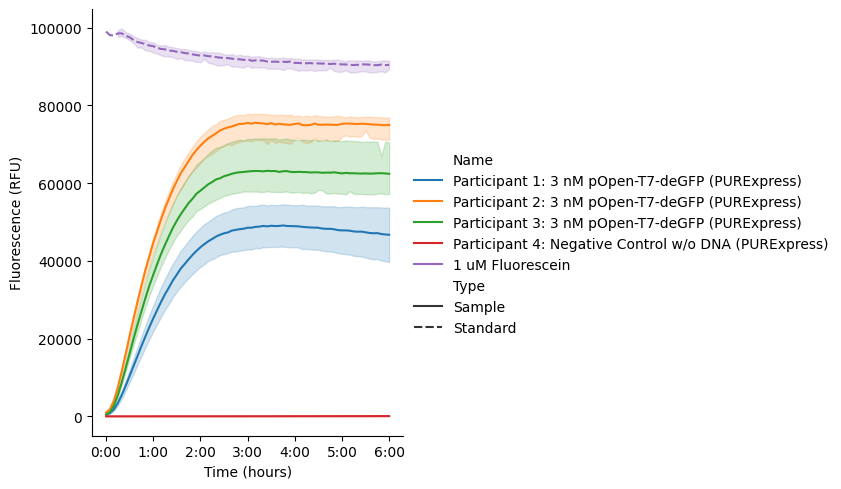
We can see that the standard (here, HPTS) is stable and can be safely used for normalization.
Normalize Data
Now, use data.normalize('<standard name>') to normalize your data. This will calculate the average over a time window at the end of the experiment (by default, 1 hour), then divide all data by the mean of that window-average across all wells with the same Name (defined by your platemap).
data = data.normalize('1 uM Fluorescein')Now replot your curves to see them normalized:
g = data.plot(style='Type', exclude_types=['Standard'])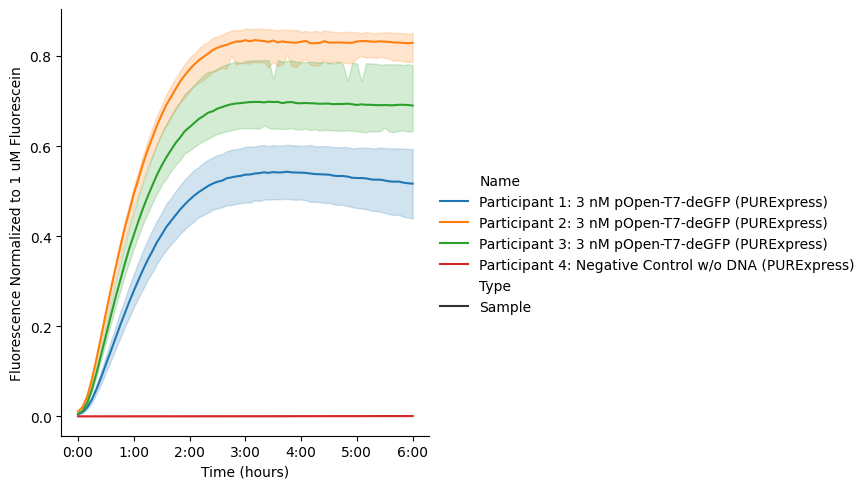
If you want to change the time window over which you calculate the average, you can use the window argument:
Kinetic Analysis
See the DevNote on kinetic analysis for more details.
Metrics extracted:
Maximum velocity: Maximum rate of fluorescence increase (slope at inflection point)
Lag time: Time to reach the exponential phase
Steady-state: Final fluorescence level
Time-to-completion: Time it takes to reach 95% of asymptote
Drift: Rate of signal decay or increase after steady-state
R²: Goodness of fit; “Good Fit” is
Trueif
# Perform kinetic analysis using sigmoid_drift model
kinetics = data.fit_kinetics()kinetics.summaryVisualize Fits
g = kinetics.plot(col="Well")
# g = kinetics.plot() # call this to visualize across replicates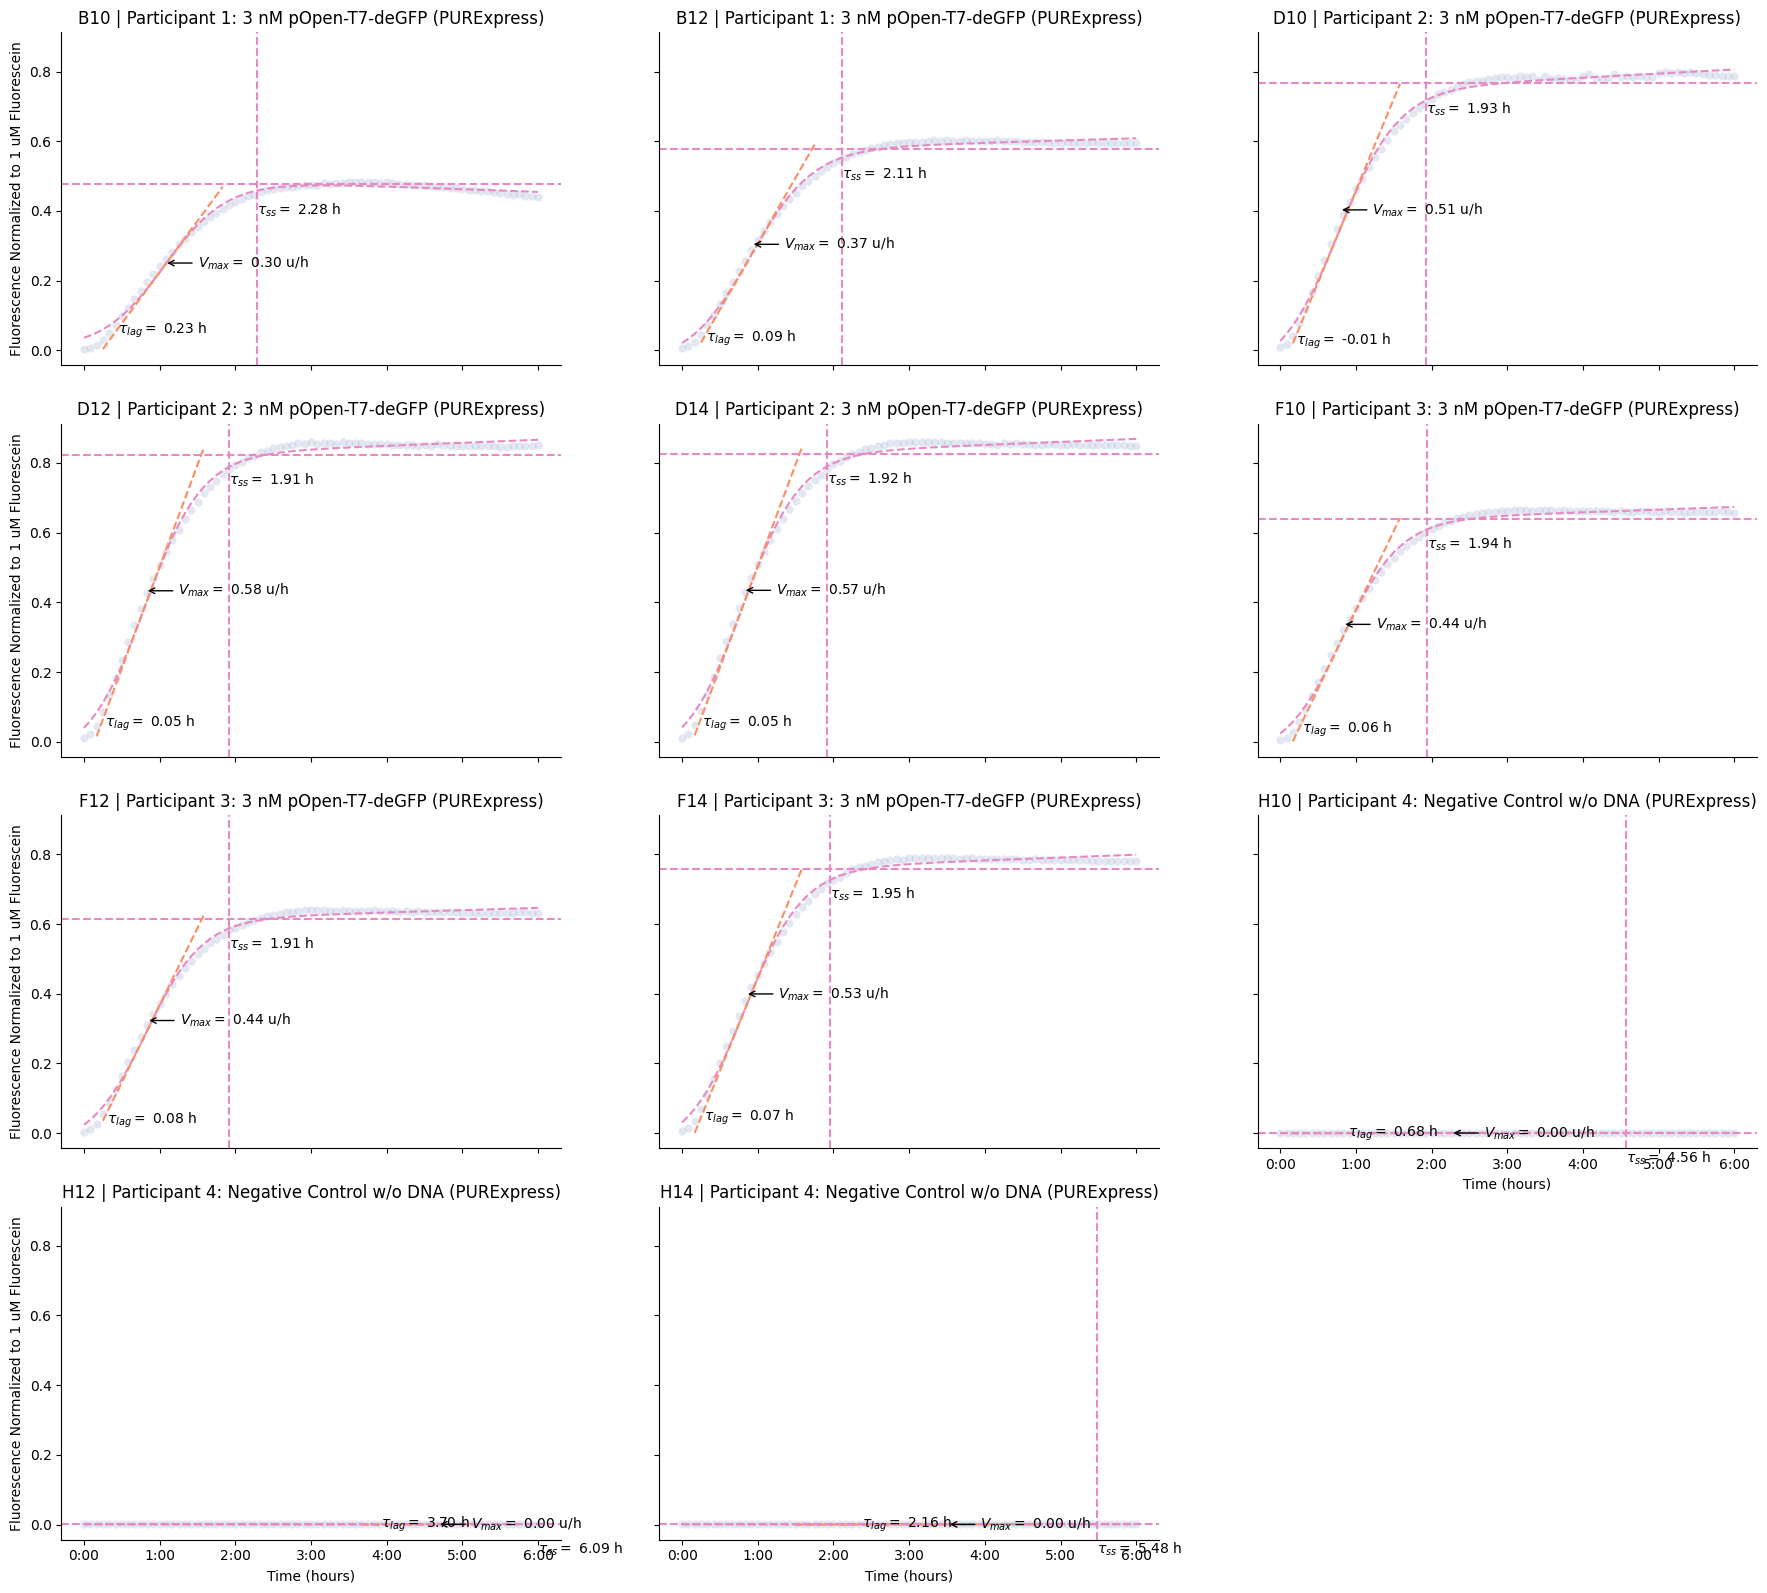
Summary Plots
g = kinetics.plot_summary()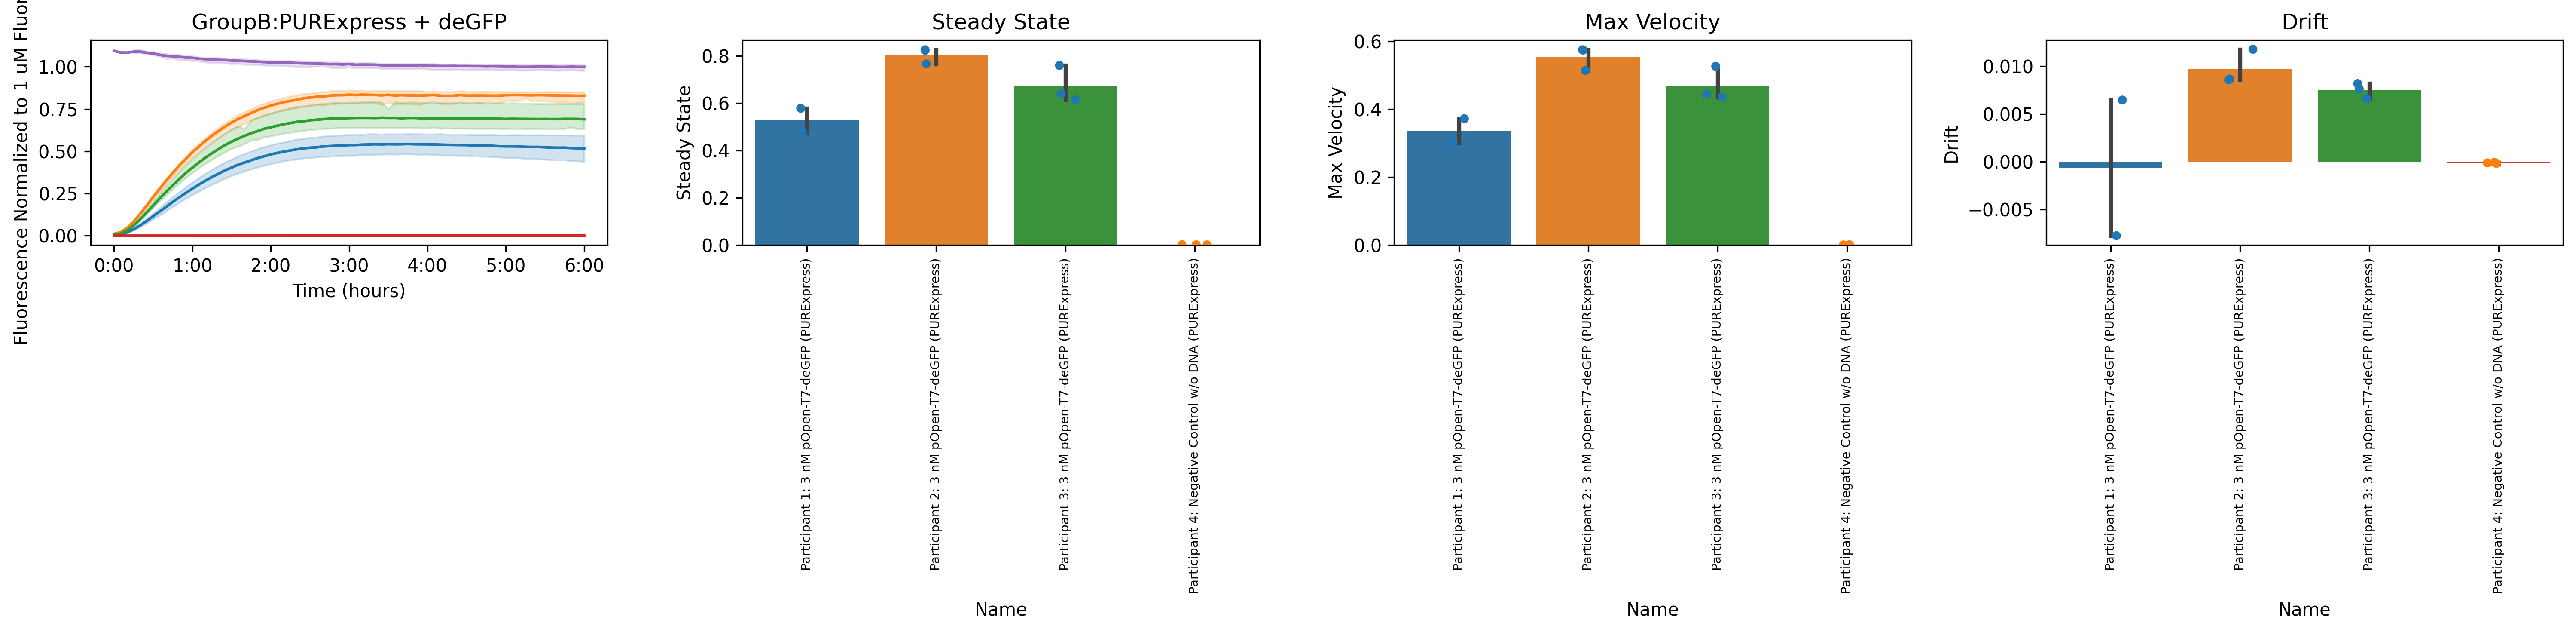
Key Metrics Explained
1. Steady-State Level (Steady State, Data)
The final fluorescence value reached by the reaction
Represents the total amount of protein produced
Higher values indicate greater expression yield
2. Maximum Velocity (Velocity, Max)
The steepest slope of the fluorescence curve (at the inflection point)
Units: RFU per second
Reflects the peak rate of protein synthesis
Sensitive to enzyme activity, substrate availability, and reaction conditions
3. Lag Time (Lag, Time)
Time before exponential fluorescence increase begins
May reflect time for ribosome assembly or initial translation steps
Shorter lag times suggest faster reaction initiation
4. Drift (Fit, drift)
Rate of fluorescence change after reaching steady-state
Positive drift: continued synthesis or aggregation
Negative drift: photobleaching, protein degradation, or quenching
Units: RFU per second
5. R² Value (Fit, R^2)
Goodness of fit (0 to 1, higher is better)
R² > 0.98 indicates excellent fit
Poor fits may indicate noisy data, overflow errors, or non-sigmoid kinetics
Tips and Troubleshooting
Overflow errors: Wells with
OVRFLWorNaNvalues are automatically excluded from fittingPoor fits (low R²): Inspect raw curves for anomalies (bubbles, evaporation, pipetting errors)
Drift: Sometimes seen in kinetics curves; use
sigmoid_driftmodelMultiple replicates: Always include technical replicates and report error bars
Comparing conditions: Normalize or blank data consistently across all samples
Next Steps
Export kinetics results:
pr.export_kinetics(kinetics, 'results.csv')Statistical analysis: Use
scipy.statsorstatsmodelsfor ANOVA/t-testsParameter optimization: Vary Mg²⁺, K⁺, or other conditions to maximize Vmax or steady-state
Mechanistic modeling: Fit ODE models to extract biological rate constants